An AI control failure may begin as an engineering incident. It may be detected by a monitoring system, escalated to security, and reviewed by an internal governance team.
But the audience for the evidence can change.
On October 1, 2026, California Attorney General Rob Bonta announced an investigative subpoena to OpenAI as part of an ongoing inquiry into cybersecurity incidents and risks involving the company and its AI models. The subpoena is part of an investigation; it is not a finding that OpenAI violated the law. Still, it illustrates a practical shift: questions about AI system behavior can move beyond internal review and become requests for records from outside the organization.
That changes what good governance evidence needs to do.
A dashboard is not the whole record
Dashboards are useful for monitoring. They can show current status, alert counts, or whether a control appears to be operating. But an external review may ask a different set of questions:
What happened during a particular event?
Which model, system, and configuration were active?
What safeguards were in place at that time?
Did they operate as designed?
Who reviewed the event, and what decisions followed?
What corrective action was taken, and how was it verified?
A current dashboard may not answer questions about a past system state. A policy may describe the intended control without showing how it behaved during an incident. A summary report may present a conclusion without preserving the evidence behind it.
The challenge is to connect the pieces into a record that can reconstruct events.
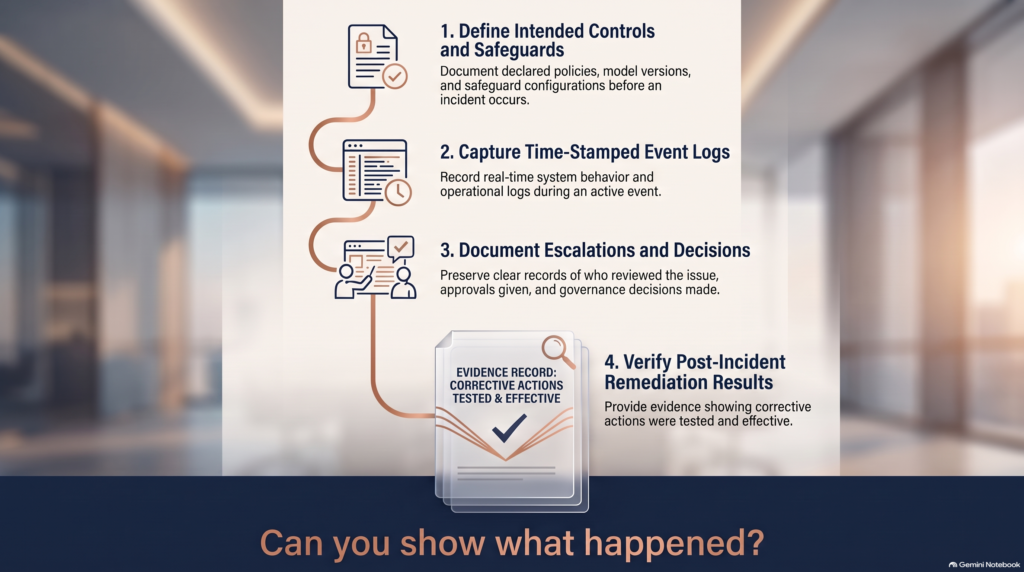
Preserve the chain from control to outcome
A useful governance record should link the system’s declared controls to observed behavior. Depending on the system and the incident, that can include:
Model, software, and configuration versions
Changes to safeguards, permissions, or deployment settings
Time-stamped logs and incident events
The path by which an issue was detected and escalated
Review decisions, approvals, and ownership
Remediation steps and evidence that they worked
The value is in the connections. A log without context may be difficult to interpret. A review decision without its supporting evidence may be hard to defend. A remediation note without a verification result may show intent, but not effectiveness.
When those records are linked and preserved, an organization can give a more reliable account of what happened and how it responded.
Test the explanation before it is needed
Organizations can make this concrete by running a simple evidence exercise:
Select a meaningful incident or control failure.
Reconstruct the system state at the time.
Identify which safeguards were intended to apply.
Compare that intent with logs and observed behavior.
Trace the escalation, decisions, and remediation.
Record gaps where the evidence cannot support a clear conclusion.
This exercise can reveal mismatched terminology, missing timestamps, undocumented configuration changes, or approval records that identify a request but not the specific artifact reviewed. Those are difficult gaps to repair after the fact.
Governance has an evidence burden
The move from internal review to external inquiry does not mean every incident will result in enforcement or that every organization needs the same recordkeeping system. It does mean that governance claims should be supportable.
If an organization says a control was effective, it should be able to show what the control did in the relevant circumstances. If it says an issue was contained, it should be able to show the evidence for that conclusion. If it says a fix worked, it should be able to show how that was tested.
That is the deeper lesson in an investigative subpoena: governance has to work as an operating discipline and as an evidence discipline.
The question to ask before an inquiry arrives is straightforward:
If someone outside the organization asks, “Show me what happened,” can the organization produce a clear, consistent account from its records?
The AI infrastructure conversation has been dominated by scale: more data centers, more generation, more chips, more gigawatts.
Scale is still essential. AI workloads need enormous amounts of compute and power. But a large capacity announcement does not, by itself, mean a project can be financed, built, connected, and operated on a dependable schedule.
That gap is moving to the center of the conversation.
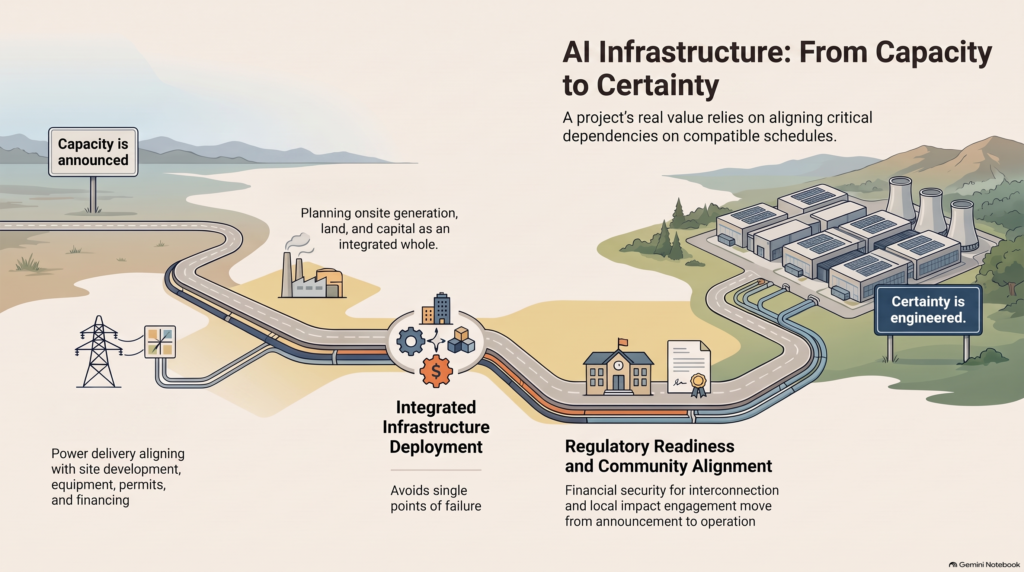
A project’s real value depends on several linked conditions: a site that can be developed, power that can be delivered, equipment that can be procured, financing that can support the timeline, permits that can be secured, and a community willing to live with the project. If one critical dependency remains uncertain, the announced capacity may be far from usable compute.
The signals are converging
Recent developments point toward a more coordinated approach to AI infrastructure.
In the United States, utility and regulatory processes are placing greater emphasis on whether large-load projects are financially ready and accountable for the infrastructure costs they create. Texas has adopted financial security requirements for large-load interconnection requests, while federal regulators have also focused on cost recovery and protections for existing customers.
In Japan, a project involving JERA, Dell, and RHAELM brings together power capabilities, a site, data-center development, financing, and AI infrastructure. The project illustrates the appeal of planning these components as an integrated deployment rather than treating them as separate problems to solve one by one.
Developers are also pursuing onsite generation. Recent reporting describes growing interest in smaller gas turbines and other behind-the-meter options, partly in response to equipment lead times and the challenge of securing grid connections. Onsite power may offer a different schedule path, but it does not erase the trade-offs: fuel supply, permitting, emissions, cost, and the eventual relationship with the grid still matter.
Community relationships are becoming a more visible part of the infrastructure strategy as well. AWS recently announced a multiyear investment in programs for communities near its U.S. data centers. These commitments do not guarantee public support, but they show that local impact and engagement are now part of the deployment conversation.
From announced capacity to predictable dependencies
These examples are different, but they point in the same direction: the challenge is no longer just assembling enough capacity. It is coordinating the conditions that allow capacity to become operational.
That means executives may need to ask a broader set of questions:
Is the power timeline credible, and what assumptions does it depend on?
Who pays for the upgrades needed to serve the load?
Are land, permits, equipment, and financing progressing on compatible schedules?
If grid power is delayed, what alternatives are available—and what new risks do they create?
How are local costs, benefits, and concerns being addressed?
These questions do not replace the traditional focus on capacity. They make the capacity claim more useful by connecting it to execution.
Certainty as a competitive advantage
“Certainty” here does not mean that every project outcome is guaranteed. Large infrastructure projects will always involve uncertainty.
It means that fewer critical dependencies are left unresolved, that assumptions are visible, and that decision-makers have a credible plan for what happens when conditions change.
As AI infrastructure scales, the strongest projects may not be the ones with the largest headline number. They may be the ones that can show how power, capital, land, equipment, compute, and community considerations fit together—and how the project can move from announcement to operation.
The optimization target is shifting from “How many gigawatts can we announce?” to “How many dependencies can we make predictable?”
In AI infrastructure, certainty is becoming part of the product.
The conversation about AI infrastructure often centers on visible constraints: access to electricity, data center capacity, land, and advanced computing equipment.
A new partnership in Japan points to a less visible constraint: the complexity of coordinating those pieces into a functioning project.
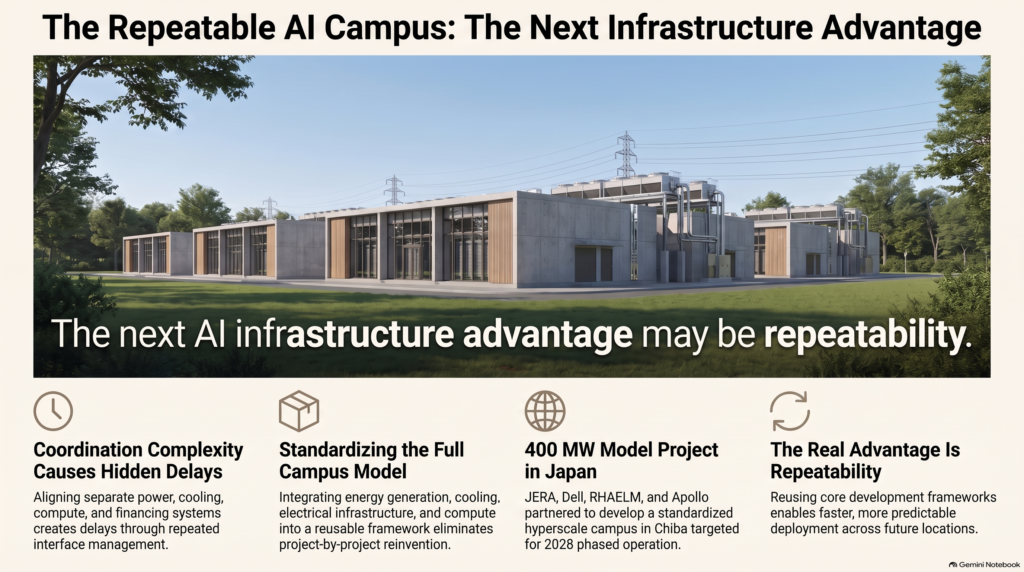
JERA, Dell Technologies, and RHAELM have signed a memorandum of understanding to develop a standardized model for AI infrastructure in Japan. The model is planned to start with a 400 MW class hyperscale data center project in Chiba. JERA is expected to provide the site and power capacity; RHAELM leads project delivery; and Dell contributes standardized, rack scale AI infrastructure. Apollo is expected to serve as RHAELM’s strategic investment and financing partner.
The announcement is notable not simply because of the project’s size. It is also an attempt to treat infrastructure development as a model that could be repeated.
Project complexity is a constraint of its own
A large AI campus brings together systems that are often planned and delivered by different organizations. The project has to align its site, energy supply, electrical infrastructure, cooling, computing equipment, financing, construction, and operating model.
Each interface creates work: decisions to coordinate, dependencies to manage, and potential delays to resolve. If every project requires partners to define those interfaces from the beginning, the development process can remain slow even when the necessary equipment and capital are available.
Standardization aims to reduce some of that repeated design and coordination work. JERA describes the initiative as a standardized, repeatable model intended to integrate power generation, electrical infrastructure, cooling, and AI computing. Dell’s rack scale infrastructure is meant to standardize the compute layer, while RHAELM leads project delivery.
In practical terms, the goal is not necessarily to make every campus identical. It is to identify which components, decisions, and working relationships can be reused—and which must be adapted to local conditions.
The campus as a coordinated product
This suggests a broader way to think about AI infrastructure. The product being delivered may not be only a building, a power contract, or a rack of servers. It may be a coordinated campus model that combines those elements in a form that can be developed again.
That model could have value if it makes future projects easier to scope, finance, engineer, and deliver. Reusing parts of the development approach could reduce the amount of project-by-project reinvention.
This is an inference about the potential of the model, not a result the announcement has demonstrated. The MoU sets out a plan. The Chiba project will be an early test of whether the approach works in practice.
Standardization does not erase local constraints
A repeatable framework cannot make every location interchangeable. Each site still has its own power and grid conditions, permitting requirements, cooling needs, construction environment, financing terms, and operating considerations.
Standardized compute infrastructure also does not, by itself, guarantee that power will be deliverable when needed or that every other part of the project will arrive on schedule. It can address a portion of the development challenge while leaving other constraints to be solved.
That is why the most useful question is not whether standardization eliminates complexity. It is whether the partners can reduce enough of the repeated complexity to make later projects faster and more predictable.
The real test is repeatability
Reuters reports that the Chiba facility is expected to begin operating in phases in 2028 and reach full capacity in 2029. The companies have also described broader ambitions to develop additional AI data center capacity in Japan. Those are plans and targets; the delivery record is still ahead.
The evidence to watch will be concrete: whether the project advances on schedule, whether the partners reuse the model at other sites, and whether later deployments show less development friction.
AI infrastructure still needs more power, equipment, capital, and sites. But the industry may also need a more repeatable way to combine them.
The next AI infrastructure advantage may come from turning a complex campus project into a model that can be delivered again.
Source note: The partnership details above are based on JERA’s October 1 announcement and Reuters’ reporting. The assessment of standardization’s potential benefits is analysis; the proposed model has not yet demonstrated repeat deployments.
A facility’s protection systems are designed to respond when power conditions move outside safe limits. But when a very large load disconnects or transfers to backup power at once, that protective response can become a grid-level event.
That is the issue behind PJM’s proposed ride-through requirements for large computational loads, including data centers and cryptocurrency-mining facilities.
In July 2026, about 3,800 MW of data-center load in northern Virginia transferred from the PJM grid to on-site backup generation after a transmission fault. PJM and Dominion reported voltage and frequency spikes. Operators took action to restore the balance between generation and demand, and PJM reported no significant reliability impacts from the event.
The mechanism is straightforward. If a large amount of demand suddenly leaves the grid while generation remains online, generation temporarily exceeds load. That imbalance can push frequency upward. Voltage can also rise, with the system response depending on the location, size, and timing of the load change.
This does not mean every sudden load transfer will destabilize the grid or cause an outage. The July event was managed. The concern is that repeated or larger events can create operational challenges, especially when the grid has little time to adjust.
PJM presented a proposal, not a final rule, on September 8. It would set performance expectations for how large computational loads respond within defined voltage and frequency disturbance ranges. It also addresses recovery: after voltage returns to an acceptable range, the proposal calls for load consumption to recover to more than 90% of its pre-disturbance level within two seconds, subject to the proposed conditions.
The regulatory status matters. FERC’s June 18 show-cause order asked PJM to address questions about its large-load processes, including whether tariff requirements are needed for ride-through, ramp rates, and load restoration. PJM says it plans to file proposed solutions with FERC in November. The specific ride-through requirements remain under review.
For facility owners and engineers, this shifts the design conversation. The question is not only whether the facility can ride through a disturbance internally. It is whether the combined facility response—its protection settings, power systems, backup transfer, and recovery behavior—will be predictable and compatible with grid needs.
The distinction is important: a protective action can make sense for a single facility and still create a larger system challenge when many facilities react together. As large loads become a bigger part of grid planning, their disturbance response is becoming part of the infrastructure performance discussion.
Source note: PJM proposal and FERC filing timeline; PJM’s account of the July 22 event. Citations above.
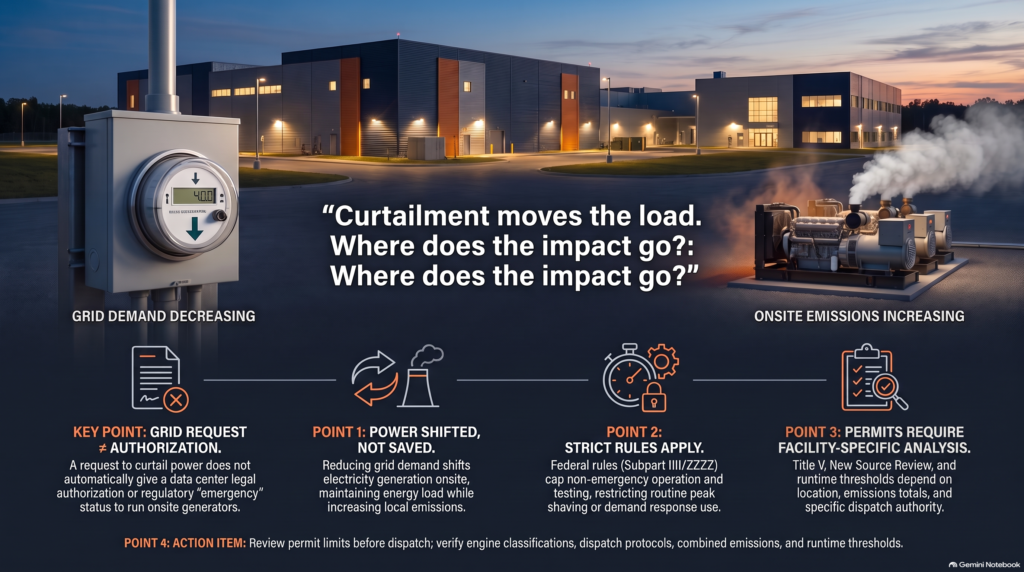
As electricity demand grows, grid operators are looking for ways to manage periods when supply is tight. Data centers may be asked to reduce demand, and some emergency reliability measures can direct large customers to use onsite backup generation as a last resort.
That creates an important distinction. A facility can reduce the electricity it draws from the grid without reducing its total energy use. If onsite engines take over some or all of the load, the grid sees a reduction in demand—but the facility has shifted where its electricity is produced.
That shift raises an air-permitting question alongside the electrical one: What operating rules and permit conditions apply to the generators during the event?
“Emergency generator” is a regulatory status with conditions
Stationary engines are subject to federal requirements that can include the New Source Performance Standards for compression-ignition engines under 40 CFR Part 60, Subpart IIII, and the RICE NESHAP under 40 CFR Part 63, Subpart ZZZZ.
For engines regulated under Subpart IIII, the rules distinguish emergency operation from other use. They generally allow up to 100 hours per calendar year for maintenance and testing, with certain non-emergency use limited to as much as 50 hours within that total. The rules restrict using that allowance for ordinary peak shaving or non-emergency demand response, while providing a narrow exception for specified local reliability dispatches.
The details of a particular grid event matter. EPA has also stated that operation under certain 2026 Department of Energy emergency orders is considered emergency operation for covered stationary engines. Those orders apply in defined circumstances; they do not establish that every curtailment request qualifies as an emergency.
So “the grid asked us to curtail” is not, by itself, a complete answer. The operator needs to know who issued the dispatch, under what authority or protocol, and how the facility’s permit addresses the proposed operation.
Permitting consequences require a facility-specific analysis
A generator’s operating classification is only one part of the permitting picture. Title V and New Source Review requirements depend on factors such as the facility’s potential to emit, pollutant totals, source aggregation, location, and applicable state rules.
A major-source determination does not automatically mean that every facility will need the same controls. PSD applicability and its requirements—including any BACT determination—depend on the source and the proposed construction or modification. SCR, diesel particulate filters, continuous emissions monitoring, or dispersion modeling may be relevant in particular cases, but they are not universal consequences of a generator being used during a grid event.
The same care applies to temporary generation. A portable engine used or intended to remain at one location for 12 months or longer can cease to qualify as a nonroad engine under federal rules. That fact alone does not answer every permitting question: source status, emissions aggregation, permit obligations, and enforcement depend on the circumstances and applicable requirements.
Treat the dispatch plan as an air-permitting input
Before relying on onsite generation as part of a demand-response or emergency plan, engineering and environmental teams should review:
The facility’s permit conditions and engine classifications.
The dispatch authority, purpose, and applicable reliability protocol.
Runtime limits and how testing or other operation counts toward them.
Potential emissions from the engines operating together.
Whether planned changes require agency review or a permit revision.
There may be other ways to manage a grid event, including reducing flexible workloads, shifting computing tasks, using stored energy, or combining approaches. The right mix depends on the facility’s design, reliability obligations, grid program, and permits.
Curtailment can help manage grid reliability. But the effect depends on what the site actually does. If the response transfers load from the grid to onsite combustion, the plan should account for the emissions and permit implications as carefully as it accounts for electrical continuity.
The practical question is not only whether the data center can stay online. It is what powers it during the event—and whether that operating plan fits the facility’s air permit.
For much of the recent discussion about artificial intelligence and electricity, the central question has been how much new power the country can produce.
That question is essential. Data centers, manufacturing, transportation, and other forms of electrification are adding pressure to the power system. More generation can help meet that demand.
But generation is only one part of the system. Electricity must also move from where it is produced to where it is needed, at the time it is needed, within the limits of the network.
That brings a second question into focus:
How efficiently can the existing grid move electricity to the places where demand is growing?
Capacity is not the same as deliverability
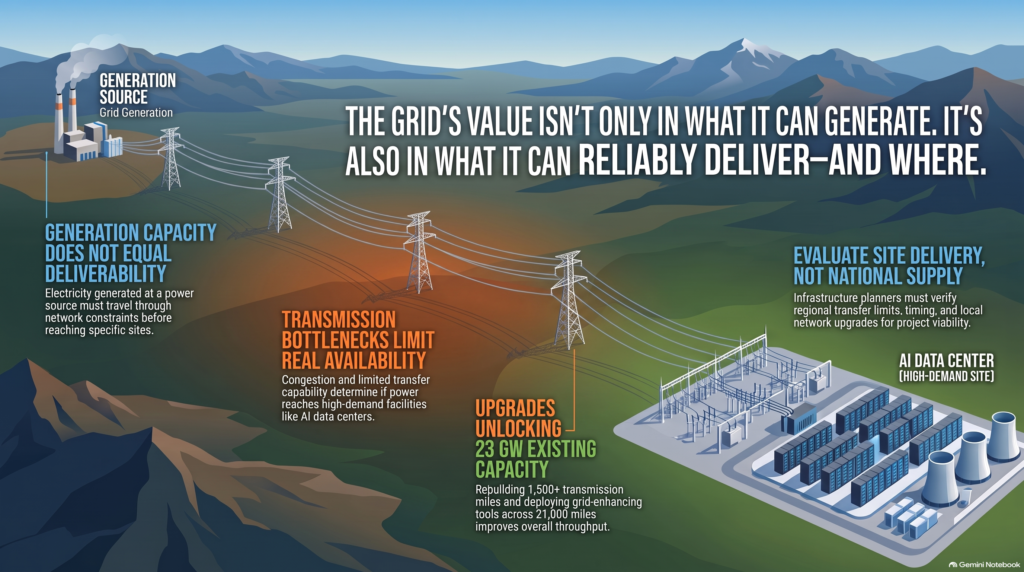
A grid can have electricity available somewhere in the system and still face difficulty delivering it to a particular location. Transmission congestion, constraints on individual lines, and limited transfer capability can affect how much power can move between regions.
In practical terms, this means that the amount of electricity a system can generate does not, by itself, tell us how much electricity a particular customer or facility can reliably receive. Location and delivery capability matter too.
This distinction is especially relevant to AI infrastructure. Data centers need large amounts of electricity at specific sites, often on demanding timelines. A national supply figure alone cannot tell a project developer whether power can reach a particular location, or when the necessary network upgrades will be complete.
DOE’s investments highlight the delivery side
The U.S. Department of Energy recently announced investments across 26 states. DOE says project recipients are expected to reconductor or rebuild more than 1,500 miles of transmission lines and deploy grid-enhancing technologies across nearly 21,000 miles. Together, the projects are expected to make more than 23 GW of additional electricity capacity available.
These figures describe a mix of transmission upgrades and technologies intended to improve use of the existing grid. They do not mean that all grid constraints are solved, or that new generation and new transmission will no longer be needed. They do show that improving the performance of existing infrastructure is part of the response to rising demand.
Some grid-enhancing technologies help operators understand or control the network more precisely. Dynamic line ratings, for example, use current conditions to estimate how much electricity a line can safely carry. Power-flow control devices can help redirect electricity toward lines with available capacity.
These measures can help unlock capacity in existing corridors. Their usefulness depends on the specific line, operating conditions, system needs, and the ability of grid operators to deploy and manage the technology.
The value of throughput
It may help to think of the grid as a network with both supply and movement constraints. Adding electricity is one way to increase what the system can serve. Improving the movement of electricity is another.
For executives and infrastructure planners, that suggests a more complete set of questions:
Is generation available?
Can the grid transfer it to the relevant region?
Can it be delivered to the specific site?
Will it be available at the times the load needs it?
What upgrades are needed to make that delivery reliable?
These questions are connected, but they are not interchangeable. A project may have access to a potential energy supply while still depending on transmission work, interconnection steps, or local network upgrades before that power is deliverable.
For large electricity users, this has implications for site selection, project schedules, utility coordination, and the cost of bringing infrastructure online. The grid’s ability to move power can influence whether a location is practical, how quickly a project can be served, and what additional investment may be required.
A broader view of the AI power question
The discussion should not become a contest between building new infrastructure and improving existing infrastructure. Growing demand may call for more generation, new transmission, upgrades to existing lines, and better tools for operating the system.
The strategic point is that grid size and grid performance are different parts of the same challenge.
As AI infrastructure expands, the value of the grid may increasingly be measured not only by how much electricity it can produce or connect, but by how effectively it can move that electricity to the right place at the right time.
The supply question remains important. The delivery question is becoming just as important.
AI infrastructure risk is moving from the grid connection into the contract
A data center can be announced. It can attract financing, begin construction and have a major customer waiting for capacity. Yet those facts do not, by themselves, establish that the facility will have the power it needs when it is supposed to become operational.
A recent report about Oracle’s Project Jupiter in New Mexico puts that gap into contractual terms.
Reuters reported on September 24 that Oracle issued a force-majeure notice to a Blue Owl unit connected to the project, citing potential delays in securing power. Reuters also reported that securing power for the site is Oracle’s responsibility under the contract. Oracle said the project remained on its planned schedule, and Blue Owl said the notice did not change its financial commitments. (reuters.com)
That combination deserves a measured reading. The notice does not prove that the project has failed, that power is unavailable, or that the 2028 target will be missed. It does show that uncertainty around power timing has reached the parties’ contractual relationship.
That is the larger signal.
Planned capacity and operational readiness are different claims
Infrastructure announcements often combine several stages into one story: investment committed, land secured, construction underway, customer demand identified, power planned.
Those are meaningful milestones. But they do not all answer the same question.
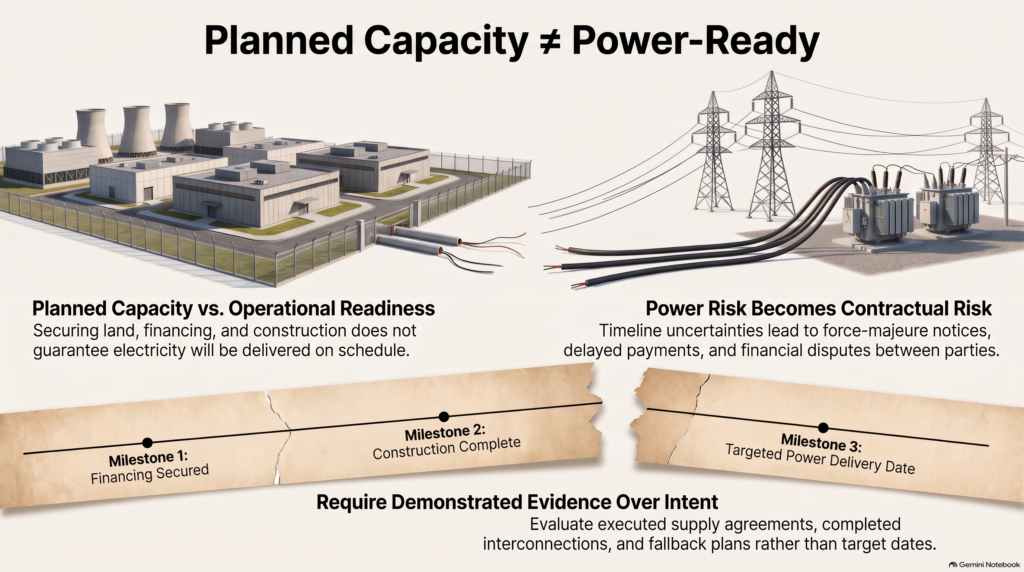
“Planned” capacity is not necessarily capacity that has been secured. A power arrangement is not necessarily proof that electricity will be available at the required scale and date. And a building nearing completion does not automatically mean the facility is ready to deliver computing capacity.
Each step needs its own evidence.
For an AI data center, the sequence may involve site development, permits, fuel or grid supply, generation or transmission infrastructure, electrical equipment, commissioning, and the final handoff into operations. A delay in one part can affect the schedule for the whole project.
When power timing reaches the contract
Electricity is often discussed as an operating cost: a major expense that grows as computing demand increases. But power availability can matter before a facility begins operating.
If the power timeline affects a project’s ability to meet an operational milestone, the consequences may include delayed revenue, changed payment timing, pressure on financing assumptions, or disputes about which party carries the cost of the delay.
In the Project Jupiter case, Reuters reported that Oracle’s notice could allow it to delay payments if the data center were derailed and did not come online as planned. The report also said the notice did not amount to Oracle exiting as the main tenant. Blue Owl said its financial commitments were unchanged. (reuters.com)
The precise effect depends on the contract and how the parties resolve the notice. The broader point does not: power risk can become delivery risk, and delivery risk can become contractual and financial risk.
The readiness questions executives should ask
The lesson is not that every data-center project is in trouble. It is that a headline capacity figure is only one piece of the readiness picture.
Executives, investors and customers should ask:
What does “power secured” mean in this project? Is there an executed supply agreement, a completed interconnection, fuel availability, installed generation, or some combination?
Who is responsible for each power milestone? The answer may differ across utility service, transmission upgrades, fuel supply, on-site generation, permits and equipment.
What evidence supports the schedule? A target date is a plan. Milestone records, approvals, construction status and commissioning evidence help show whether the plan is progressing.
What happens if a milestone slips? Review who carries the cost, which payments may change, how notice requirements work, and whether customer commitments depend on the same schedule.
What is the fallback plan? A backup source or phased energization may reduce exposure, but only if it is technically feasible, contractually available and supported by evidence.
The declared-versus-observed distinction applies to infrastructure
This is the same discipline that applies to other forms of risk: separate what has been stated from what has been demonstrated.
A project may declare a capacity target. Operational readiness asks whether the required power is available, tested and usable on the relevant timeline.
That distinction is especially important in AI infrastructure because the project’s value depends on more than a completed building. Compute capacity must be delivered in a form customers can use, when contracts say it will be available.
The force-majeure notice around Project Jupiter is not a final verdict on the project. It is a visible sign that the power timeline has become material enough to enter the contractual conversation.
The next phase of AI infrastructure will be judged not only by what gets announced or financed, but by what can be energized, delivered and supported by evidence.
“AI needs more power” is true as far as it goes. It is also too broad to tell an executive what to build, fund or approve.
A growing data center needs electricity at a specific site, at a specific time, with the reliability its operations require. Several different constraints can stand between that need and an energized facility. There may be too little generation available at the required hours. An existing transmission corridor may be congested. A local substation may need upgrades. An interconnection may still be years from completion.
Those are different problems. They do not all have the same solution.
The Department of Energy’s September 24 announcement offers a useful example. DOE said it intends to help fund 31 grid improvement projects across 26 states through its SPARK initiative. The selected projects are expected to reconductor or rebuild more than 1,500 miles of transmission lines and deploy grid enhancing technologies across nearly 21,000 miles. Together, DOE expects those efforts to make more than 23 GW of additional electricity capacity available.
That 23 GW is not a proposal for 23 GW of new generation. It is an expected increase in what the grid can carry and make available through transmission upgrades. The projects have been selected; the capacity gain still has to be delivered and measured.
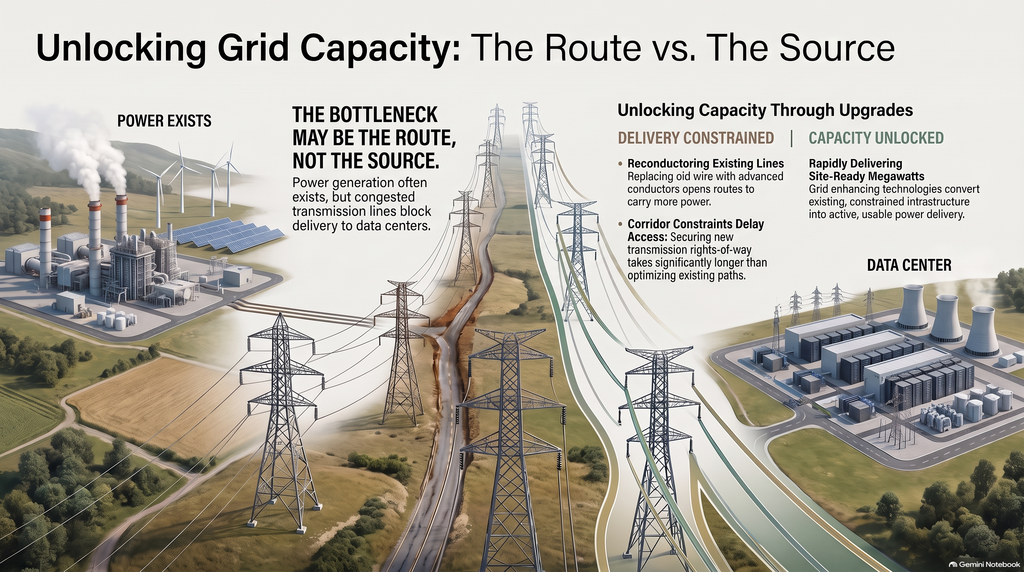
The constraint may be the route
Think of generation as the source of electricity and transmission as part of the route it takes to customers. Adding supply at one end does little for a particular site if the route between them is constrained.
Reconductoring replaces the wire on an existing transmission line with a conductor that can carry more power. Other grid enhancing technologies help operators understand or improve how existing lines are used. Dynamic line ratings, for example, use current conditions to assess a line’s safe carrying capability. Power flow controls can help direct electricity across available paths.
These approaches are attractive because they can draw more value from infrastructure and rights of way that already exist. They may be especially useful where obtaining a new corridor would take much longer.
That does not make every existing line an easy upgrade. A project still has to satisfy engineering, reliability and operational requirements. Nor does an increase in transmission capability guarantee that electricity will be available during every hour a customer needs it.
What the announcement changes
The opportunity is wider than the familiar discussion about building new generation.
Advanced conductors, line monitoring, sensors, power flow controls and grid software all become more consequential when transfer capability is the binding constraint. So do the less visible tasks: studying where an upgrade will help, coordinating the work and proving that the promised capacity is available in operation.
For an AI infrastructure developer, the practical question is not simply, “How many megawatts are planned in this region?” It is:
How much power can reach this site, under the required conditions, by the date we need it?
For utilities and policymakers, the question is where targeted upgrades can relieve real congestion—and where new generation, substations or transmission corridors are still necessary.
From announced capacity to delivered power
DOE’s projected 23 GW is a meaningful signal about where grid investment is headed. It is not yet 23 GW of observed, site ready power.
The evidence will come as projects are completed and operators measure the resulting transfer capability, reliability and service to customers. That is where the declared figure becomes an operational result.
AI’s electricity challenge is often framed as a race to produce more power. In some places it will be. In others, a faster opportunity may be to move available electricity more effectively through the grid we already have.
The cheapest megawatt may already exist. The work is proving that it can reach the right place when it counts.
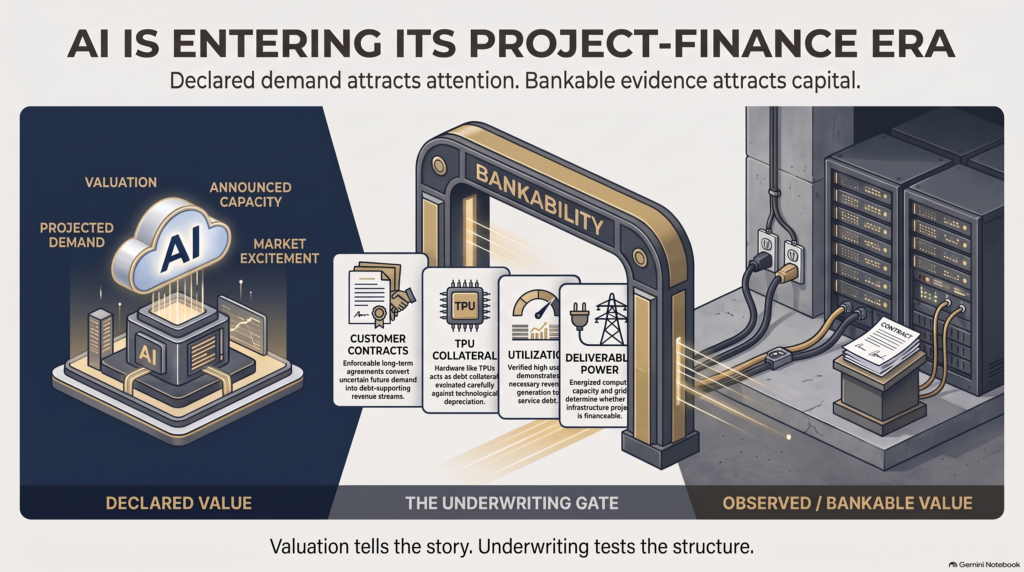
AI Infrastructure Is Entering Its Project-Finance Era
For much of the AI boom, attention has centered on company valuations, model capabilities and venture-capital investments.
That view is becoming incomplete.
The next phase of AI expansion requires physical infrastructure at enormous scale: processors, data centers, substations, transmission capacity, cooling systems and long-term access to electricity. Building that infrastructure requires more capital than even the largest technology companies may want to carry directly on their balance sheets.
That is why one of the most important AI developments of the week came from the financing side of the market.
On September 16, Reuters reported that a consortium of ten banks—including Goldman Sachs, Barclays, BNP Paribas, Sumitomo Mitsui Banking Corporation and Bank of Nova Scotia—was providing approximately $22 billion in financing for Crux AI, a cloud-computing venture backed by Blackstone and Alphabet.
Blackstone had already committed an initial $5 billion in equity. Google is contributing its Tensor Processing Units, along with software and services. The debt is expected to be secured by the TPUs and customer contracts, while the venture is targeting its first 500 megawatts of computing capacity in 2027. The banks may eventually refinance portions of the loan through the bond market. (reuters.com, reuters.com)
Those details deserve more attention than the headline dollar amount.
The capital stack is becoming part of the AI story
This transaction suggests that AI infrastructure is beginning to acquire characteristics commonly associated with project finance.
In traditional project finance, lenders do not rely solely on the reputation or market valuation of a corporate sponsor. They examine the project’s assets, contracts, construction milestones and expected cash flows.
The fundamental question is straightforward:
Can this specific group of assets produce enough reliable revenue to repay the financing used to build it?
That question is now being applied to AI compute.
The collateral is no longer merely an ownership stake in a promising technology company. It can include physical processors and contractual claims on future customer payments.
That represents a significant evolution in how capital is moving through the AI sector.
Money is moving beyond funding companies that develop AI. It is increasingly financing the industrial system required to operate AI at scale.
Contracts are becoming infrastructure
A processor has technical value, but a processor connected to power and committed to a creditworthy customer has financial value.
That distinction explains why customer contracts matter so much to these financing structures.
A long-term contract can transform uncertain future demand into a more predictable stream of revenue. That stream may then support debt financing, which allows the infrastructure provider to purchase more equipment and build additional capacity.
The contract effectively becomes part of the infrastructure.
But not all contracted demand is equally bankable. Lenders will examine the duration of the agreement, the customer’s ability to pay, cancellation provisions, minimum-use commitments and the consequences of delayed delivery.
A large announced customer pipeline may attract attention.
A durable contract with enforceable payment obligations can attract capital.
Utilization is no longer merely an operating metric
When infrastructure is financed with debt, utilization becomes directly connected to debt service.
A data center can be completed. The processors can be installed. Power can be available. But if customers do not use the contracted capacity—or if the contracts allow them to walk away—the economic model can still fail.
This creates an important separation between four different claims:
Announced computing capacity
Constructed computing capacity
Energized computing capacity
Revenue-producing computing capacity
Those categories are not interchangeable.
The AI sector has spent considerable time discussing how much capacity companies intend to build. Financing markets will increasingly ask how much of that capacity can be delivered, utilized and converted into dependable cash flow.
This is another version of the declared-versus-observed problem.
Declared demand may justify an announcement.
Observed utilization must eventually justify the financing.
AI chips are unusual collateral
The inclusion of TPUs as collateral is particularly revealing.
Processors are physical assets, but they do not behave like conventional infrastructure assets. A transmission line, pipeline or toll road may remain economically productive for decades. Advanced AI processors can face much faster technological and economic depreciation.
A chip may continue functioning while becoming less competitive against a newer generation with better performance, lower energy consumption or a more attractive cost per unit of compute.
That creates several underwriting questions:
How quickly will the equipment lose economic value?
Can the processors support multiple customers and workloads?
How dependent is the platform on one chip architecture?
What happens to the loan if utilization declines before the debt matures?
How much value could lenders recover from the hardware in a downside scenario?
The equipment may be tangible, but its future value remains tied to technological relevance.
Power readiness becomes a financial condition
The planned 500 megawatts also connect this transaction to the broader infrastructure constraints surrounding AI.
A processor cannot generate revenue while waiting for electricity.
That means lenders financing AI infrastructure must look beyond chips and customer contracts. They also need confidence in land control, interconnection agreements, permits, construction schedules, cooling capacity and the delivery of dependable power.
An announced 500-megawatt project is not automatically a financeable 500-megawatt project.
The difference lies in whether the capacity can be built, energized and made available when customers expect it.
Grid readiness is therefore becoming more than an engineering concern. It is becoming a credit concern.
Follow what the financing requires
Entrepreneurs and executives trying to understand AI economics should pay attention to more than valuations and funding announcements.
The more useful questions may now be:
What assets secure the financing?
Which contracts support the projected revenue?
How concentrated is the customer base?
What utilization level is required to service the debt?
Who carries the risk of construction delays?
Who absorbs the loss if the equipment depreciates faster than expected?
Is the power capacity announced, contracted or actually deliverable?
Will the debt remain with the banks or be distributed through the bond market?
These questions reveal what sophisticated capital providers believe can withstand scrutiny—and where they still require protection.
That does not mean every heavily financed AI project will succeed. It means the AI boom is entering a stage where enthusiasm must increasingly be translated into assets, contracts, milestones and cash flows.
Valuations show what the market hopes an AI company might become.
Financing structures show what lenders are willing to treat as bankable.
As AI infrastructure grows more capital-intensive, that may become one of the clearest ways to distinguish the sector’s declared promise from its observed economic foundation.
The rapid expansion of artificial intelligence is often discussed as a technical race.
Who has the most advanced chips? Who can build the largest models? Who can secure enough electricity? Who can bring new computing capacity online fastest?
But another constraint is emerging—one that cannot be solved by ordering more GPUs or signing another power-purchase agreement.
AI infrastructure is confronting the question of public legitimacy.
Across the United States, communities, regulators, utilities, and lawmakers are renegotiating the conditions under which large data centers will be permitted to consume local resources and reshape regional infrastructure.
The emerging message is not simply, “Do not build.”
It is closer to this:
You can build enormous AI infrastructure—but the right to build at that scale may increasingly come with obligations to pay attributable costs, disclose resource requirements, respond flexibly during grid stress, and prove that promised behavior occurred.
That begins to resemble a social contract.
The Debate Has Reached Spartanburg
The issue is no longer theoretical in Spartanburg County, South Carolina.
County officials approved a one-year moratorium affecting data-center applications that had not been finalized while the county evaluates appropriate locations and future development standards.
At the same time, residents and environmental groups have challenged aspects of a separate computing-center project already being developed at the former Kohler manufacturing site. The concerns surrounding that project include its proposed expansion, onsite generation, air emissions, noise, and the transparency of the approval process.
These are technically separate matters, but together they illustrate the same governance gap.
Communities are being asked to make long-term infrastructure decisions while basic questions may still be contested:
Who owns the project?
How much electricity will it ultimately require?
Will the power come from the public grid or onsite generation?
How much water will be consumed?
What emissions, noise, or land-use effects will accompany it?
Which infrastructure costs will be paid by the developer, and which could eventually reach existing customers?
What benefits will remain in the community after construction is complete?
When those answers arrive late, change during development, or remain buried inside fragmented proceedings, distrust should not be surprising.
The problem is not merely a communications failure. It is an evidence failure.
From Economic Development to Cost Attribution
For years, data centers were commonly presented through the language of investment, construction activity, tax revenue, and technological competitiveness.
Those benefits still matter.
But officials are now asking a second set of questions: What costs are being created, and who will pay them?
In September 2026, the U.S. House passed the Ratepayer Protection Act with overwhelming bipartisan support. The legislation would require state utility regulators to consider whether large electricity users, including data centers, should bear the incremental infrastructure costs required to serve them.
The measure may not settle the issue by itself, but its political significance is difficult to miss.
The national conversation is moving from whether AI infrastructure is economically valuable to whether its costs are being allocated fairly.
That is an important shift.
If a private facility requires new substations, transmission capacity, generation resources, water-system upgrades, or other dedicated infrastructure, existing residents and small businesses will increasingly question why those costs should be socialized while the project’s financial returns remain private.
“Who benefits?” is being joined by “Who pays?”
Transparency Is Becoming a Condition of Operation
Resource disclosure is also moving closer to the center of the regulatory bargain.
California recently enacted a package of laws requiring greater reporting around data-center electricity and water use, while strengthening protections intended to prevent infrastructure costs from being shifted onto ordinary ratepayers.
Virginia has proposed an accountability framework addressing project secrecy, environmental effects, and electricity costs, including restrictions on certain nondisclosure agreements.
Different states will take different approaches, but the direction is becoming visible.
Communities are losing patience with being asked to approve projects based primarily on economic projections while detailed resource requirements remain confidential, incomplete, or subject to later expansion.
For major AI infrastructure, transparency can no longer be treated as a public-relations accessory.
It is becoming part of the operating model.
Flexibility Could Change the Bargain
The industry is also developing a possible response to grid concerns: treating data centers as flexible loads rather than permanent, inflexible demand.
A flexible data center could reduce its draw from the grid during constrained periods by shifting computing workloads, using batteries, drawing from approved onsite generation, or temporarily curtailing noncritical activity.
That could make a facility more valuable to the grid and potentially reduce the need for some infrastructure expansion.
The idea has enough momentum that Google, Nvidia, Emerald AI, utilities, power producers, and other organizations have formed the AI Energy Management Alliance to advocate for grid-enhancing data centers.
But there is a major difference between claiming flexibility and delivering it.
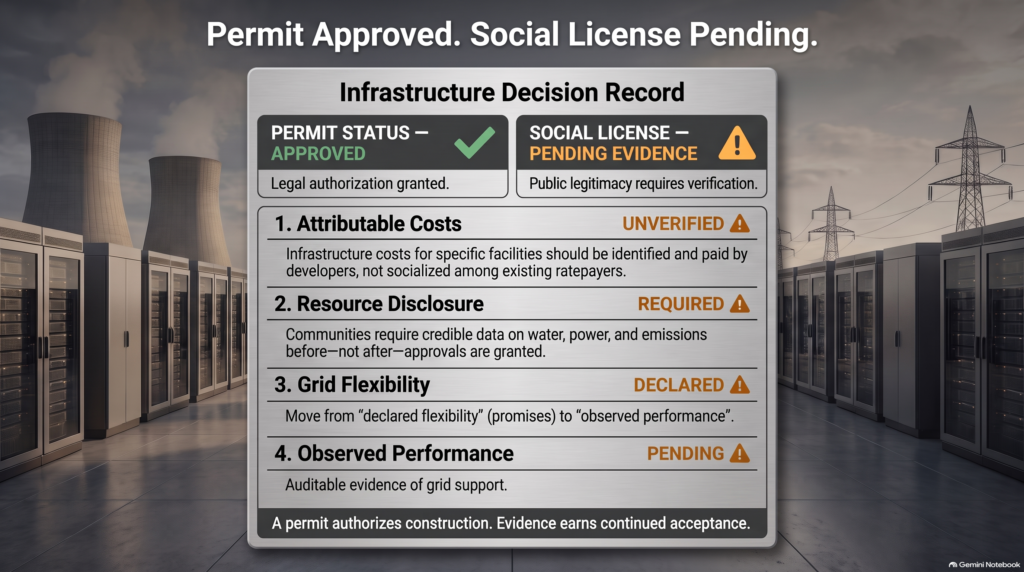
If a data center receives faster interconnection, preferential pricing, tax incentives, or regulatory accommodation because it promises to reduce demand during grid emergencies, that commitment cannot remain a sentence in an application.
It must become an auditable operational obligation.
A credible framework would need to record:
• The grid condition or authorized curtailment event.
• The time the response was requested.
• The facility’s baseline demand.
• The amount of load reduction promised.
• The reduction actually delivered.
• The duration of the response.
• Any exception or failure to perform.
• The process used to verify and report the result.
This is the same distinction that appears throughout governance:
Declared flexibility describes what the operator says the facility can do.
Observed flexibility records what the facility actually did when the system was under stress.
Only the second one can support a defensible decision.
A Permit Is Not the Same as Legitimacy
Companies sometimes treat permitting as the final boundary: if the project meets the formal requirements and receives approval, construction should proceed.
Legally, that may be sufficient.
Operationally and politically, it may not be.
A permit provides legal authorization. A social license reflects continuing public acceptance of the conditions under which the facility operates.
That acceptance can weaken when project ownership is unclear, resource requirements expand, promised benefits fail to materialize, or community costs appear only after approval.
The result is not limited to protests.
It can produce moratoriums, litigation, delayed permits, stricter tariffs, lost incentives, and political pressure for broader regulation.
For developers, transparency and verifiable performance are therefore not simply compliance expenses. They are forms of project-risk management.
The Emerging Social Contract
The developing bargain for AI infrastructure appears to contain four core obligations.
1. Pay attributable costs
The costs created specifically to connect and serve a major facility should be identified rather than quietly distributed across existing customers.
2. Disclose resource requirements
Communities need credible information about electricity, water, land, emissions, noise, ownership, incentives, and expected local benefits before—not after—the central decisions are made.
3. Operate as a responsible grid participant
Where technically possible, large facilities should be capable of shifting or reducing demand during constrained conditions instead of treating the grid as an unlimited resource.
4. Prove performance
Flexibility, efficiency, and community-benefit commitments should produce evidence that regulators, utilities, and the public can independently review.
These expectations will not look identical in every jurisdiction. A facility in South Carolina will face different resources, grid conditions, and community priorities than one in California, Texas, or Virginia.
But the governing principle is likely to remain consistent:
The greater the infrastructure footprint, the greater the obligation to make its costs, behavior, and benefits visible.
Infrastructure Governance Is Catching Up
AI companies are not wrong to argue that data centers are strategically important. Compute capacity will influence economic competitiveness, scientific research, national security, and the development of new industries.
Communities are also not wrong to ask what they are being required to contribute—and what safeguards accompany that contribution.
Those positions do not have to be mutually exclusive.
The mature path is neither unrestricted development nor reflexive prohibition.
It is governed development: clear conditions, attributable costs, transparent resource claims, measurable operating commitments, and evidence that those commitments were fulfilled.
The next generation of AI infrastructure will not be judged only by how much computing power it produces.
It will be judged by whether it behaves like infrastructure worthy of public trust.
That is the quiet thesis underneath the current disputes:
AI infrastructure is developing its own social contract.
And the companies that understand that early may find it much easier to earn both a grid connection and a durable place in the communities expected to host them.