Tag: AIInfrastructure

  • AI Data Centers Are Becoming Large Enough to Require New Reliability Rules

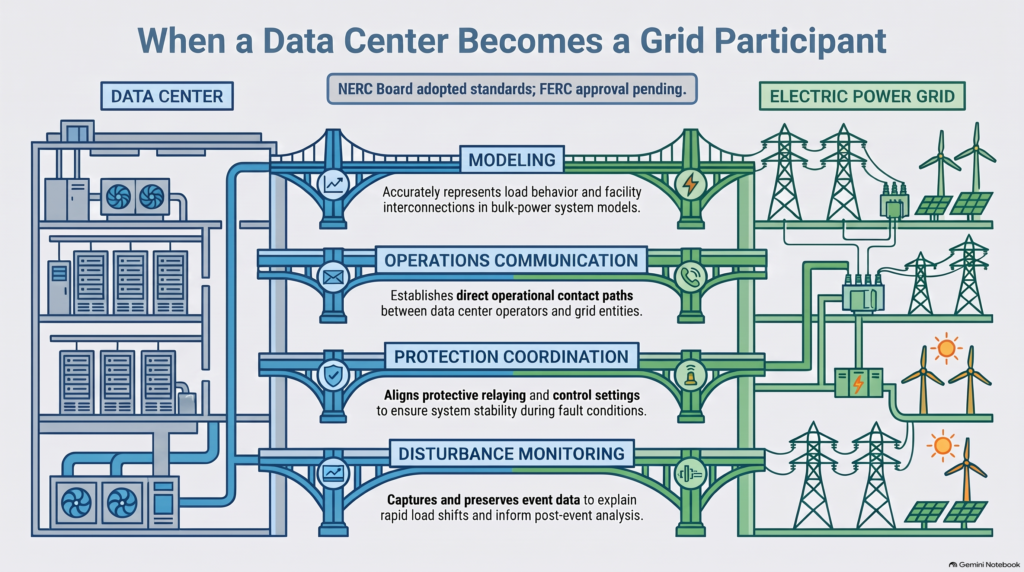
    The growth of large computational loads is changing the operating relationship between data centers and the electric grid. NERC’s new standards point toward a more formal governance model—one that connects facility operations, engineering, and executive oversight to bulk-power-system reliability.

    A data center can be highly resilient inside its fence and still create risks at the grid interface.

    That distinction matters as AI facilities, data centers, and other computational loads grow in scale and connect to the bulk power system. Their electrical demand can change quickly, and their response during a disturbance can affect more than the facility itself. Grid operators need timely information about the load, credible models of its behavior, and clear communication with the people who operate it.

    NERC’s proposed computational-load reliability standards are an effort to establish that foundation.

    From stakeholder ballot to regulatory review

    On October 15, NERC announced that the standards and their implementation plans had passed their final stakeholder ballot. On October 26, NERC’s Board of Trustees adopted the standards. NERC has said it will submit them to the Federal Energy Regulatory Commission for approval in the United States. Until FERC approves them and the applicable implementation period arrives, they are not enforceable U.S. reliability standards. (nerc.com, nerc.com)

    The proposed registry criteria would apply to Computational Load Owners and Computational Load Operators at sites with total connected load of at least 50 MW, supplied through electrical equipment connected at 100 kV or higher. This is a proposed registration threshold—not a claim that every data center or large electricity customer is covered. The related registry criteria also have a separate approval path. (publicpower.org, nerc.com)

    What the standards address

    NERC’s first phase centers on basic capabilities needed to integrate large computational loads reliably. The proposed standards address how loads are interconnected and represented in system models; how facility operators communicate with relevant grid entities; and how protection coordination and disturbance monitoring support reliable operation. The project materials identify three foundational standards—CLO-001-1, CLO-002-1, and CLO-003-1—alongside related revisions to interconnection requirements and studies. (nerc.com)

    These requirements matter because grid reliability depends on a shared operational picture. If the load changes unexpectedly, operators need to understand what happened, how the facility responded, and whether similar behavior could recur. Reliable models, clear communications, coordinated protection, and usable disturbance records help make that possible.

    The governance question for executives

    The standards create a practical governance challenge: responsibility may be split among the entity that owns the site, the entity that operates it, the data-center tenant, the utility, and other grid participants. NERC’s registry revisions establish distinct Computational Load Owner and Computational Load Operator roles, underscoring the need to identify who is accountable for each operational duty. The proposed registry criteria remain subject to FERC approval. (nerc.com)

    Executives should begin with a clear map of ownership and accountability:

    • Assign a responsible executive. Give one leader authority to coordinate energy, engineering, operations, compliance, and external grid relationships.
    • Clarify owner and operator responsibilities. Document who maintains models and protection settings, who communicates with grid entities, who responds to disturbances, and who preserves records.
    • Assess operational readiness. Review procedures, contact paths, escalation authority, and after-hours coverage. A contact list that works only during business hours is not an operating plan.
    • Review data and model quality. Confirm that technical information shared with grid operators reflects current facility design and actual operating behavior.
    • Connect contracts to operating reality. Agreements with tenants, operators, utilities, and service providers should support timely information sharing and coordinated action.
    • Prepare evidence of control. Keep records that show how the facility manages communications, models, protection coordination, and disturbance response.

    This work is useful before a rule becomes enforceable. The goal is not to guess at final compliance obligations; it is to identify gaps early enough to resolve unclear responsibilities, missing data, and fragile operating procedures.

    A first phase, not the finish line

    NERC describes the adopted standards as the first phase of its broader large-load action plan. Additional standards work is underway around computational-load performance, planning and reliability studies, event reporting, and model quality. (nerc.com)

    That points to a wider shift in how data-center readiness will be judged. Power availability, backup generation, and facility uptime remain essential. But large computational facilities also need to show that their grid-facing behavior is understood, communicated, and governed.

    For boards and executive teams, the strategic question is straightforward: Can the organization explain who is responsible for the facility’s effects on the grid, how those responsibilities are carried out, and what evidence shows the controls work?

    As computational loads grow, reliability will depend on that answer being clear before the next disturbance—not reconstructed afterward.
  • Time to Power: Why Grid Delays Can Become Contract Risk for AI Infrastructure

    AI infrastructure projects are often described through large, attention-grabbing numbers: megawatts, GPUs, investment totals and planned opening dates. But those figures only tell part of the story. For a customer planning cloud or AI services, capacity matters when it is ready to use.

    The planned Nscale site in Loughton, Essex, offers a concrete example of how the schedule can break down.

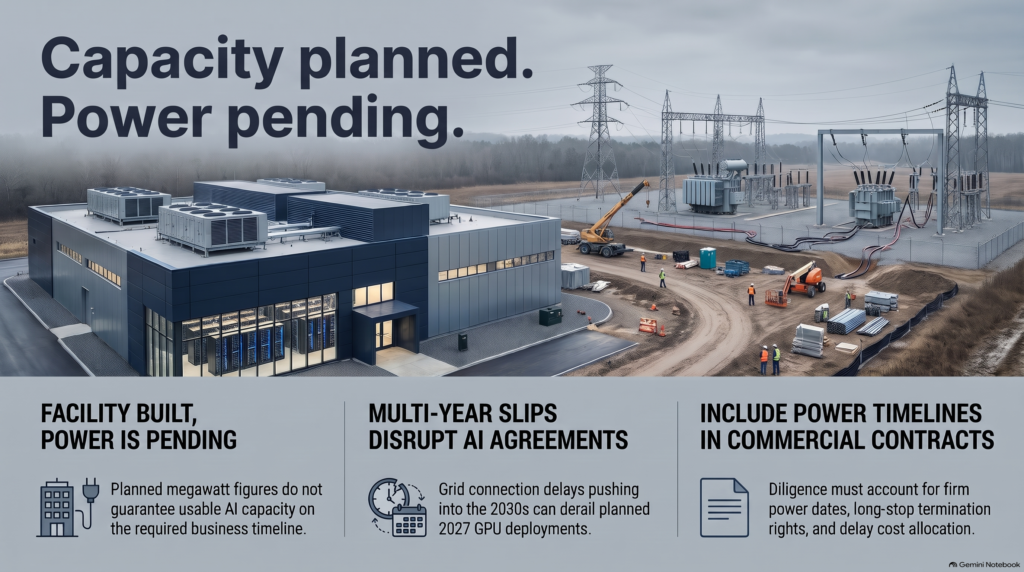
    Reuters reported that Microsoft withdrew from its agreement for capacity at the site after the expected grid connection slipped into the 2030s. Nscale had planned a facility with 50 MW of AI capacity, scalable to 90 MW, and approximately 23,040 Nvidia GB300 GPUs for Microsoft Azure. The original announcement anticipated GPU delivery beginning in early 2027. 

    Microsoft said its decision related to one site and reaffirmed its wider partnership with Nscale. Nscale said it remained committed to Loughton and was exploring alternative power sources and other UK expansion sites. The public reporting does not disclose the contract’s terms, the exact termination provision or the financial consequences for either party. 

    A project schedule depends on more than construction

    Data centre readiness depends on several linked pieces: the building, electrical equipment, cooling, network connectivity, hardware and sufficient power. If one critical dependency arrives years later than planned, the rest of the investment may not produce its expected value on schedule.

    That creates commercial consequences. A late power connection can postpone the point when a customer can use capacity, delay revenue, extend the time capital is tied up and create uncertainty about whether demand will still be there when the site is ready. These are general project risks; the publicly available details do not establish which of them applied to this specific agreement.

    Why this can become a contract issue

    Long-term infrastructure agreements have to allocate the risks of delay. Executives and project teams should understand how the contract treats power availability, delivery milestones, delay thresholds, customer remedies and termination rights.

    The questions are practical:

    • Is the power date confirmed, estimated or dependent on future grid work?
    • What happens if service begins later than the customer’s required date?
    • Is there a defined long-stop date after which a party can exit?
    • Can capacity be moved to another site or supplied from another source?
    • Who bears added costs while the project waits?

    These are questions to raise during commercial and legal review—not assumptions about the terms of Microsoft’s agreement.

    The executive takeaway

    A planned megawatt figure doesn’t guarantee usable capacity on the date a business needs it. Time to power affects whether a project can support customer commitments and whether its economics still work when the facility is ready.

    The better diligence question is not only, “How much AI capacity will this project deliver?” It is also, “When will power be available, how certain is that date, and what happens contractually if it moves?”

    In AI infrastructure, the power schedule belongs in the commercial plan from the start.

  • The Next AI Infrastructure Bottleneck May Be Electrical Cable

    AI infrastructure is often discussed through its most visible assets: advanced chips, enormous data centers and new sources of power. But those assets only become a functioning system when the supporting electrical infrastructure is available and connected.

    Electrical cable is one of those less visible dependencies—and it may be harder to scale quickly than project announcements suggest.

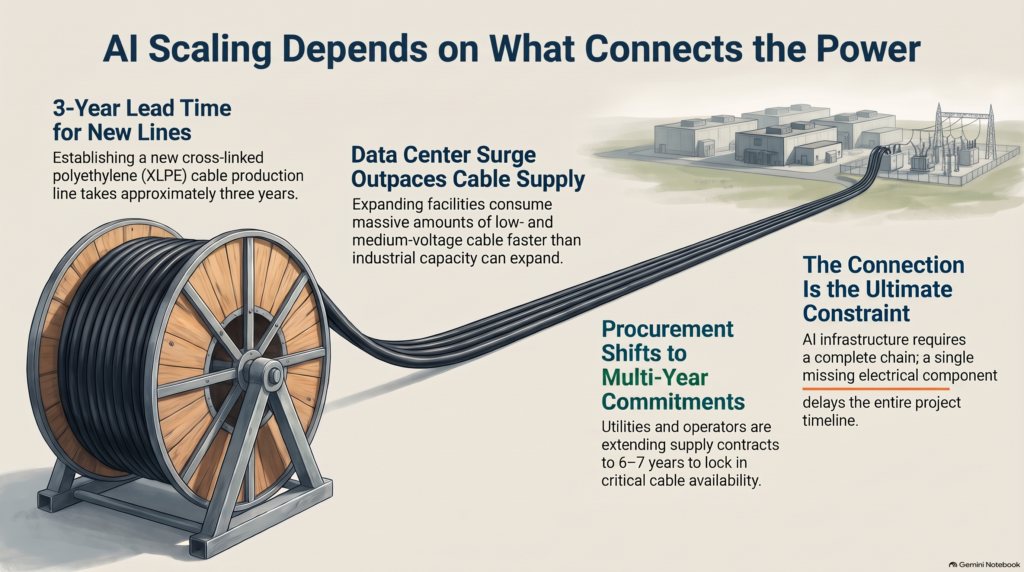
    On October 22, Reuters reported that Nexans CFO Vincent Piquet said cable production capacity is emerging as a bottleneck for AI-driven data-center construction. He described global capacity as tight and said that establishing a new cross-linked polyethylene (XLPE) cable production line, known in the industry as a CV line, takes around three years. 

    That estimate needs to be read precisely. It concerns the time required to establish a new production line. It does not mean that every cable order has a three-year delivery time, nor does it establish that all cable categories are constrained to the same degree.

    Why cable matters to data-center construction

    A data center is not simply a building filled with servers. It needs electrical systems that bring power into the site and distribute it through the facility. Reuters reported that data centers require large amounts of low- and medium-voltage cable for those connections, with larger facilities consuming proportionately more medium-voltage cable. 

    That creates a timing challenge. Demand for a project’s power infrastructure can rise faster than manufacturers can add capacity. Even when a developer has secured land, financing or computing equipment, the project still depends on the availability of components needed to connect and distribute electricity.

    The mismatch is between project urgency and industrial lead time. Data-center developers may want to move quickly, while manufacturing expansion requires investment, equipment, skilled labor and time to bring new lines into service.

    Procurement is already adapting

    The Reuters report also described a change in procurement behavior: French distribution network operator Enedis has moved from annual agreements to contracts lasting six or seven years to secure cable supply. That is one example of a buyer seeking more certainty through longer commitments; it should not be generalized to every market or customer. 

    Still, it points to a wider planning question. When essential components are scarce or slow to expand, procurement becomes part of infrastructure strategy. Buyers may need earlier demand forecasts, longer supplier relationships and clearer visibility into which projects will actually proceed.

    Where the opportunity may be

    The opportunity is broader than cable manufacturing alone. It may include:

    • Manufacturers able to expand the specific cable capacity the market needs.
    • Suppliers of specialized materials, production equipment and related components.
    • Procurement teams that secure supply early and coordinate across project schedules.
    • Developers and utilities that identify long-lead electrical components before construction is underway.

    These are possible areas of opportunity, not guarantees of demand or financial returns. The specific product, market, customer commitments and ability to deliver all matter.

    Nexans’ own October 22 financial release provides a concrete company response: it said it is investing to expand medium-voltage production capacity in Europe and the United States, with data centers among the markets it aims to serve. That confirms Nexans is adding capacity in that area; it does not show that the broader supply constraint has been resolved. 

    The bigger lesson for AI scaling

    The cable story fits a recurring pattern in infrastructure development: the component that limits progress may not be the one receiving the most attention.

    AI capacity depends on a sequence of linked systems—generation, grid connections, substations, electrical distribution, cooling, buildings and computing equipment. A delay in one essential layer can affect the schedule of the whole project.

    For executives, the practical question is not only how much capacity has been announced. It is whether the critical components can be manufactured, delivered and installed on the timeline the project assumes.

    A data center can be planned in megawatts. It still has to be built one connection at a time.

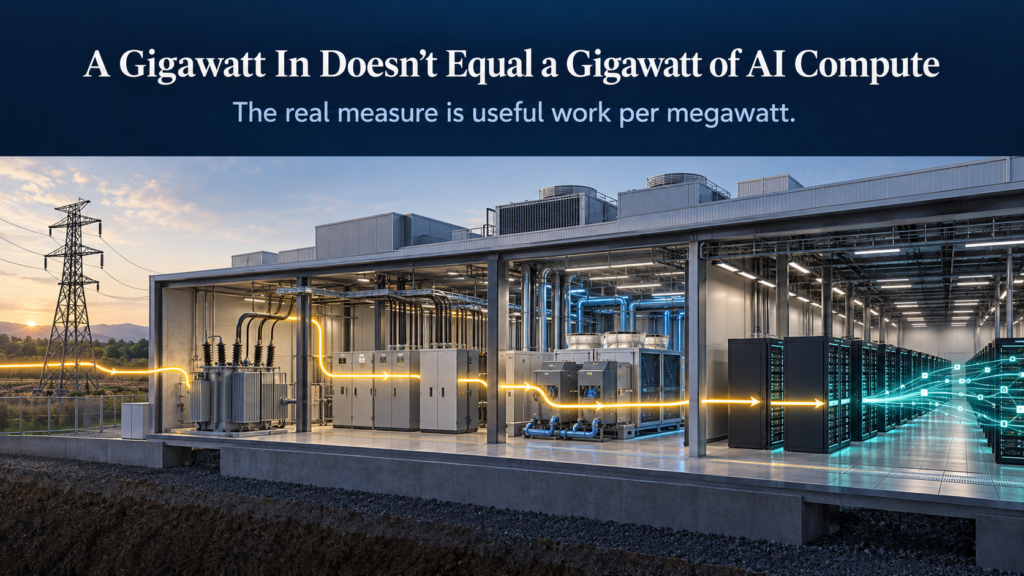
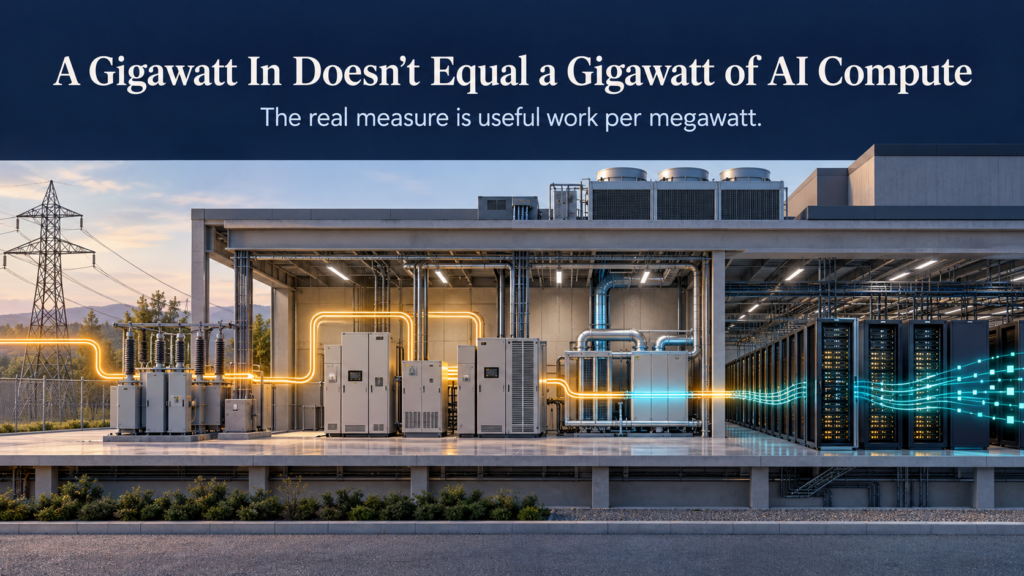
  • Why a Gigawatt of Electricity Doesn’t Mean a Gigawatt of AI Compute

    A data center’s power capacity tells us how much electricity it can draw. It does not tell us how much useful AI work the facility will produce.

    That difference matters as companies compete for power, build larger campuses, and commit billions of dollars to AI infrastructure. A megawatt secured at the grid connection is only the beginning of the measurement.

    Power has to travel through the system

    Electricity entering a data center must be converted and distributed before it reaches computing equipment. The facility also needs cooling, monitoring, backup systems, and other infrastructure to operate reliably.

    Then there is the equipment itself. A GPU can be installed and powered without running at full utilization. A poorly configured rack, a failed component, or a system restart can reduce productive output even while the facility continues to draw power.

    The result is a gap between electricity consumed and useful computation delivered.

    What the reported 60–70% estimate tells us

    On October 14, TechRadar reported remarks from NVIDIA representatives at a Vertiv event suggesting that roughly 60–70% of electricity drawn by some AI data centers supports AI processing. The report described the remaining share as associated with cooling, power distribution and conversion, equipment configuration, failures, and restarts.

    That figure is an industry estimate reported from executive remarks. It is not an independently audited average for all data centers. Facility design, workload, equipment, climate, operating practices, and the way “AI processing” is measured can all affect the result.

    The estimate is still useful as a prompt: capacity figures alone do not reveal how efficiently a facility turns electricity into productive work.

    “Non-compute” power is not automatically waste

    Cooling and backup systems are necessary to keep high-density computing equipment within operating limits and protect service continuity. Power conversion and distribution are also part of delivering electricity safely to the IT load.

    The goal is not to eliminate every watt that does not go directly to a processor. The goal is to understand the full system, reduce avoidable losses, and make sure the infrastructure investment supports dependable output.

    A facility designed for peak demand and contingencies may also have capacity that is not used continuously. That may be appropriate for resilience, but it raises a management question: how much of the available infrastructure is producing useful work under typical operating conditions?

    Measure the output, not just the input

    “Gigawatt of AI compute” is shorthand. A gigawatt measures electrical power; compute output is measured through completed work and system performance.

    For executives, that means asking for more than a facility’s contracted power or nameplate capacity. Useful measures could include:

    • Electricity delivered to the facility and to IT equipment
    • AI workload throughput, such as completed jobs or tokens generated
    • Accelerator utilization and periods of idle or degraded operation
    • Cooling and power-system overhead
    • Availability, restart frequency, and time spent operating below target

    These measures need consistent definitions and a clear time period. A peak result, a design target, and an observed operating average are different kinds of evidence.

    The strategic implication

    When power is scarce, improving the amount of useful computation produced from existing electricity can be as important as securing more supply.

    That makes infrastructure efficiency an operating and capital-allocation issue. Better power delivery, cooling, equipment configuration, workload scheduling, and maintenance may help increase productive output without assuming that every problem can be solved by adding another megawatt.

    The reported 60–70% estimate should be treated as a signal to investigate, not a benchmark to apply blindly. Each operator needs facility-level evidence to understand where power goes and what work it enables.

    The executive question is therefore not only, “How much power can this data center draw?”

    It is: How much useful, reliable AI work does each megawatt deliver—and how do we know?

  • The Grid Can Track AI Demand. But Who Has Authority to Control It?

    FERC’s PJM decision separates load visibility from curtailment authority

    The growth of AI infrastructure is making electricity demand harder to forecast and plan around. Large data centers can require hundreds of megawatts, ramp up over time, and depend on power arrangements that affect regional reliability planning.

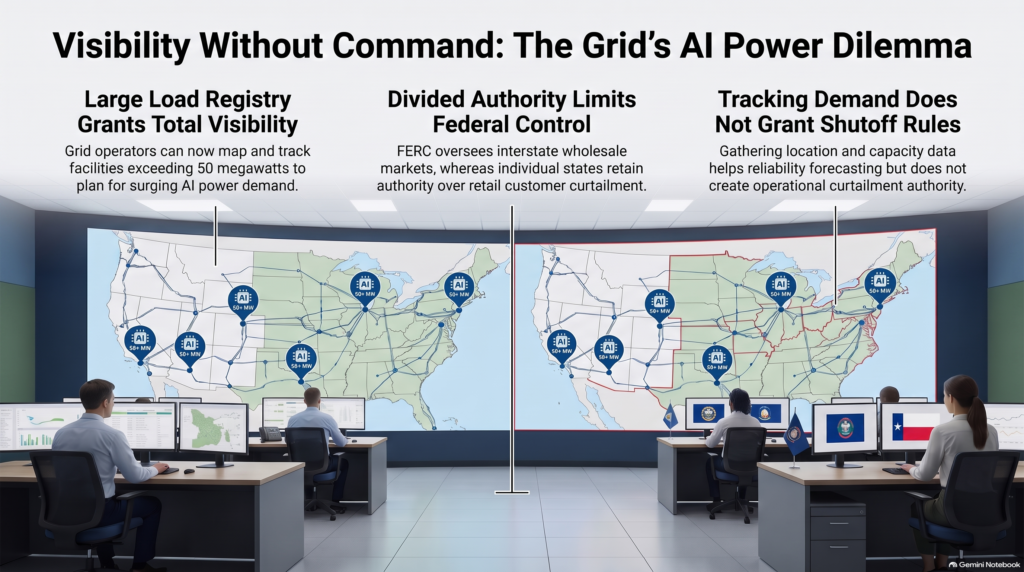
    On October 9, 2026, the Federal Energy Regulatory Commission (FERC) took a step toward improving visibility into that demand. It approved PJM Interconnection’s definition of a “Large Load” and its proposed Large Load Registry. At the same time, FERC rejected much of PJM’s broader proposal for providing interim service to new large loads, including provisions related to curtailment. (elibrary.ferc.gov, utilitydive.com)

    The decision highlights an important regulatory distinction: collecting information about large electricity users is different from deciding when their service can be interrupted.

    What the registry is meant to show

    PJM’s approved definition covers end-use customer load with a cumulative peak of at least 50 megawatts at a single electrical site. The registry is designed to collect information such as a facility’s location, ramp schedule and capacity supply. That information can help PJM understand how large loads may affect forecasts and reliability planning. (elibrary.ferc.gov, utilitydive.com)

    A registry improves visibility. It can help answer questions such as:

    • Where is major new demand expected to connect?
    • How quickly is that demand expected to ramp up?
    • What capacity supply is associated with the load?

    Those are important planning questions. But data collection does not itself create an operational curtailment rule or settle which regulator has authority over a retail customer’s service.

    Why FERC rejected the broader proposal

    PJM’s filing also proposed an Interim Resource Adequacy Service framework for certain new large loads. Under parts of that proposal, eligible loads that did not bring their own new capacity could face load-reduction requests as the system approached an emergency.

    FERC rejected that framework. The Commission said several provisions appeared to place obligations directly on large loads that are, for the most part, retail customers; to dictate which retail customers would be curtailed; and to establish a retail compensation rate. It also found that PJM had not adequately shown that the proposed treatment of those loads would avoid undue discrimination. (utilitydive.com)

    This is where jurisdiction matters. FERC oversees interstate transmission and wholesale market rules. States have a central role in regulating retail electricity service, including determining which retail customers may be curtailed when the system is stressed. FERC’s order treated the issue as a shared regulatory challenge, not as a simple question of whether grid operators can see or manage demand. (utilitydive.com)

    What the decision does—and does not—mean

    The order does not mean large data centers are exempt from every form of curtailment, or that emergency load reduction is off the table. It addresses the specific tariff framework PJM proposed in this filing. FERC also gave PJM direction on issues it would need to address if it revises and resubmits parts of the proposal. (utilitydive.com, headwaterswire.com)

    The distinction is between three separate layers:

    1. Visibility: identifying large loads and gathering information about them.
    2. Grid operations: maintaining system reliability as supply and demand change.
    3. Decision rights: determining which customers can be asked or required to reduce demand, under what rules, and with what protections.

    The registry advances the first layer. The order shows that the third requires careful coordination across federal and state authority, as well as rules that can be defended as fair.

    The governance question behind AI power demand

    For AI infrastructure, the practical issue is not only how much electricity a facility may use. It is also whether the grid and regulators have clear, workable rules for what happens when demand exceeds available supply.

    That requires a complete chain: reliable information about large loads, transparent criteria for reliability actions, clear responsibility for issuing those actions, and consistent treatment across customer classes. Without that chain, the grid may know where demand is growing while decision-makers remain uncertain about who can require it to change.

    The registry can help the grid see the load. It cannot, by itself, determine who has authority to control it.

    Source: FERC, Docket ER26-3515-000, order issued October 9, 2026.

  • The Next AI Megawatt May Come From a Power Plant We Already Built

    As demand for electricity grows, the conversation often turns to new generation: new plants, new transmission, and new infrastructure. Those investments matter. But a recent Google–Constellation agreement points to another part of the supply equation: increasing output from assets that are already operating.

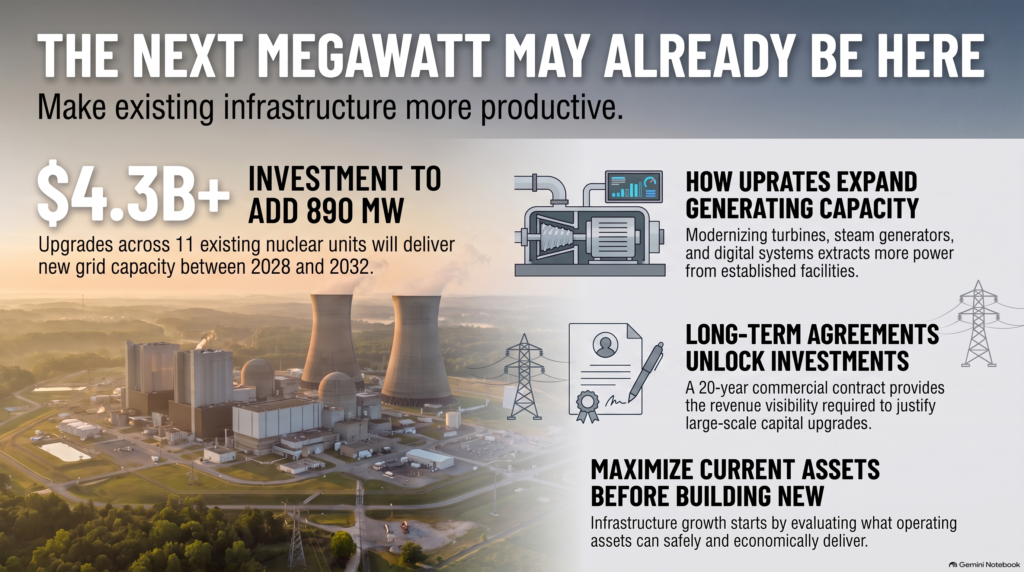
    Announced October 6, the companies’ 20-year power purchase agreement supports upgrades at 11 existing Constellation nuclear units across six sites in Illinois, Pennsylvania, and New Jersey. The upgrades are expected to add 890 megawatts of nuclear capacity to the PJM grid. Constellation says it plans to invest more than $4.3 billion in the work. The first uprate is expected in 2028, with the full 890 MW planned by the end of 2032. 

    This is not a new nuclear plant coming online today. It is a long-term investment plan to increase output from existing reactors.

    What an uprate changes

    A nuclear uprate increases a plant’s generating capacity by upgrading equipment and systems. The companies cite work involving turbines, steam generators, and digital control systems. The goal is to produce more electricity from an existing facility while maintaining the requirements that govern its safe and reliable operation. 

    That distinction matters. An operating plant already has a site, grid connections, and much of the supporting infrastructure. Upgrading it may offer a different development path from building a new facility. But it still requires substantial capital, specialized engineering, regulatory work, construction planning, and time.

    Why the commercial structure matters

    The 20-year agreement provides a long-term customer commitment associated with the planned upgrades. That kind of revenue visibility can help a generator justify capital investment in equipment and capacity improvements.

    The agreement also sits within a larger power arrangement. Google and Constellation signed a separate 15-year supply contract for another 2,700 MW from Constellation’s PJM generation fleet. That supply is not linked to a specific generating source, so it should not be counted as part of the 890 MW of new nuclear capacity. 

    The distinction between the two agreements is useful: one supports planned incremental nuclear capacity; the other provides long-term revenue certainty for existing generation assets.

    The capital-efficiency lesson

    Capital efficiency does not mean avoiding investment. In this case, the announced program includes more than $4.3 billion in planned investment. The efficiency question is whether targeted upgrades to existing assets can add useful capacity while making productive use of infrastructure already in place.

    That is a different question from simply asking how quickly a new plant can be built. It asks whether the current system contains assets with additional potential—and what investment, operational changes, and approvals are needed to realize it.

    The answer will vary by asset and location. An upgrade is not automatically faster, cheaper, or feasible everywhere. The 890 MW is a target for future delivery, with the first uprate expected in 2028 and the full capacity planned by the end of 2032. 

    A broader infrastructure principle

    For executives assessing electricity needs, the agreement offers a useful lens: examine both new supply and the productivity of existing assets. In power, that can mean evaluating uprates, reliability, grid connections, operating performance, and demand flexibility alongside new construction.

    The broader lesson applies across infrastructure. Growth does not always begin with acquiring or building another asset. Sometimes it begins by asking what the current asset base can safely and economically deliver—and what commitment will make the required investment possible.

    The next megawatt may come from a new plant. It may also come from making an existing one work harder.

    Source note: Constellation’s announcement says 890 MW will be added to the PJM grid through the planned nuclear upgrades; Google’s post provides the end-of-2032 target. The separate 2,700 MW agreement is not source-specific. 

  • The Electrical Bottleneck Inside the AI Data Center

    AI power discussions often begin outside the data center: Can the grid serve the load? Is generation available? How long will interconnection take? Can transmission capacity reach the site?

    Those questions remain central. But they aren’t the only ones.

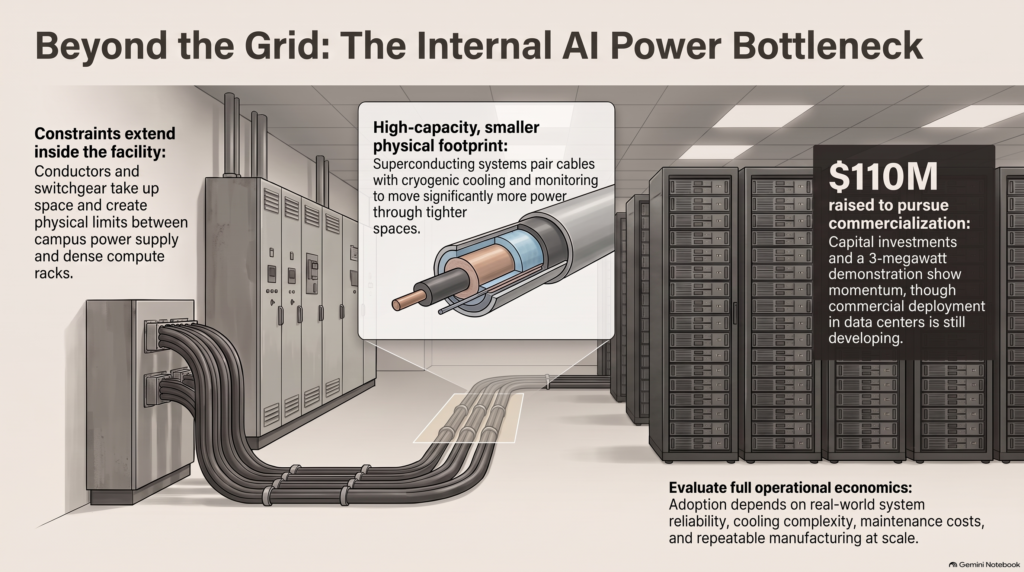
    After electricity reaches a campus, it must still pass through the facility’s electrical infrastructure and arrive at the equipment that performs the computing. That pathway has physical limits. Conductors, switchgear and other equipment take up space, require installation labor and must operate reliably under demanding conditions. As data centers add more power-dense computing, the electrical system inside the facility becomes part of the scaling challenge.

    VEIR’s October 8 financing announcement is a signal that investors see an opportunity in this layer. The company announced a $110 million Series C, bringing its reported total capital raised to $225 million. It says the funding will support manufacturing, product development and preparation for commercial deployments. VEIR also reports a 3-megawatt demonstration and says it is working with customers and industry partners on reference designs for AI facilities. 

    The approach centers on superconducting power-delivery systems. In VEIR’s description, the system includes more than the superconducting cable: it also requires cryogenic cooling, controls, terminations and monitoring. The goal is to move more power through a smaller physical footprint than conventional power-delivery infrastructure. 

    That could matter where space and power density are becoming linked. A smaller footprint could give designers more flexibility inside a facility or campus. But a compact cable alone doesn’t establish an operational advantage. The complete installation has to work as a system, and its economics must account for cooling, controls, installation, maintenance and the consequences of equipment failure.

    The technology also addresses a specific point in the power chain. It may improve how electricity is distributed within a data center. It does not supply the electricity, secure an interconnection or expand the grid. Those are separate constraints, and they remain part of the larger project.

    That distinction is useful because “AI needs more power” can make every proposed solution sound interchangeable. They aren’t. Some investments add generation. Some expand transmission. Others improve the way power is delivered inside a facility. A project may need progress at several of these layers at once.

    The commercial evidence is still developing. VEIR’s reported 3-megawatt demonstration is a technical milestone, while the company’s announcement describes initial commercial deployments as something it is preparing for. Reuters reported earlier this year that superconducting cables were not yet being used in data centers and that cost and manufacturing constraints had limited adoption. 

    For operators and infrastructure investors, the next questions are practical:

    • How reliably does the full system operate under real data-center loads?
    • What does it cost to install and maintain compared with conventional alternatives?
    • How does the cooling and control equipment affect operating complexity?
    • Can the system be manufactured, installed and serviced repeatedly at commercial scale?

    The $110 million round indicates investor confidence in the opportunity and provides capital to pursue commercialization. The test of the thesis will be what commercial deployments show about reliability, economics and repeatability.

    AI infrastructure can be constrained at more than one point between the grid and the server. Power availability gets attention because it is visible and difficult to solve. Power delivery inside the facility may be less visible, but it can also shape how densely and efficiently a campus grows.

    The useful question is not just how much electricity a data center can secure. It is how dependably and economically that electricity can be delivered to the compute.

    Source note: VEIR’s financing and technical milestones are company-reported; treat commercial performance claims as unproven until supported by operating data.

  • FERC’s Pause on PJM’s Backstop Plan Shows Why Speed Needs Structure

    A regulatory fast-track can shorten a process. It cannot make unresolved obligations disappear.

    On September 29, FERC acted on PJM Interconnection’s proposed Reliability Backstop Procurement, or RBP. PJM designed the one-time procurement to secure additional capacity after its 2028/2029 capacity auction fell approximately 6,800 MW short of the region’s reliability target. The plan was intended to help address a near-term supply gap amid rapid load growth, including demand from data centers. 

    FERC accepted parts of PJM’s proposal but suspended it for five months, with an effective date of February 28, 2027, while opening further proceedings on unresolved provisions. PJM confirmed that the procurement would not begin on September 30 as originally planned. The commission also asked PJM to improve its data-center demand forecasts. 

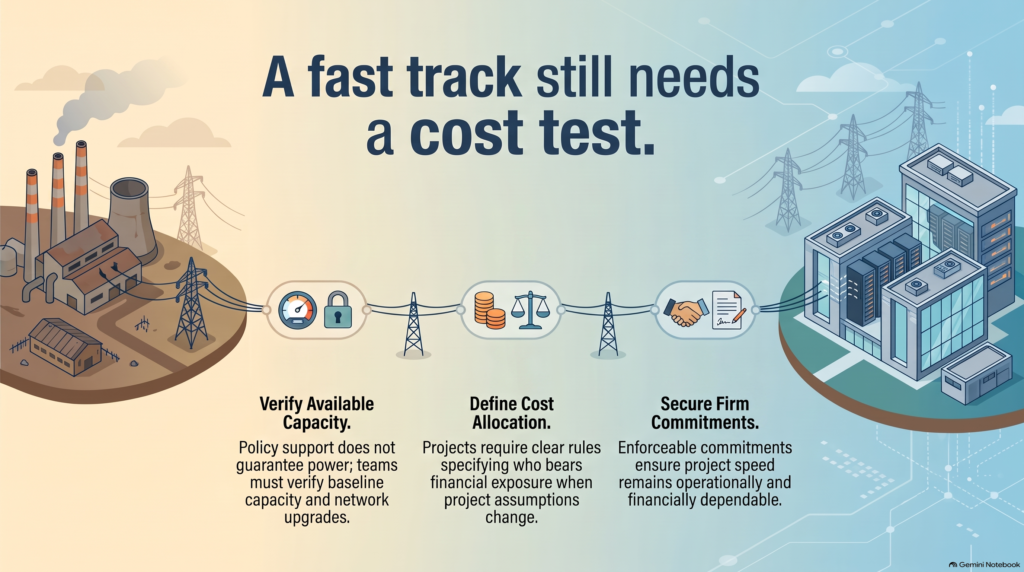
    The issues are practical, not procedural trivia. PJM identified concerns around cost allocation, transmission-owner exit rules, and collateral requirements for load-serving entities. Those rules shape who bears financial exposure if the procurement moves forward, and whether the obligations remain dependable over time. 

    That makes this a useful infrastructure-planning signal: a mechanism designed to move quickly can still be delayed if its allocation of costs and risks is not sufficiently defined. FERC did not say the region does not need new capacity. Its order accepted core elements while requiring more work on how the proposal would function.

    The distinction between this case and “fast-track interconnection” also matters. The RBP is a capacity procurement. PJM’s Expedited Interconnection Track is a separate process for qualifying new generation projects, and FERC approved that track separately. Calling the RBP pause the “death of shortcut interconnections” would merge two different mechanisms and draw a broader conclusion than the order supports. 

    For developers and large energy users, the practical takeaway is to treat policy support as one input to a project plan—not as proof of available power. Before relying on a site or procurement pathway, teams should verify the relevant capacity, interconnection status, needed network upgrades, enforceable commitments, and who carries the costs if assumptions change.

    PJM’s case illustrates a broader principle: speed can help a project move, but clear rules make that speed usable. The next advantage may belong to developers who can show not only that they have a path to power, but that the path is operationally and financially credible.

  • AI Infrastructure Is Moving From Maximum Capacity to Maximum Certainty

    The AI infrastructure conversation has been dominated by scale: more data centers, more generation, more chips, more gigawatts.

    Scale is still essential. AI workloads need enormous amounts of compute and power. But a large capacity announcement does not, by itself, mean a project can be financed, built, connected, and operated on a dependable schedule.

    That gap is moving to the center of the conversation.

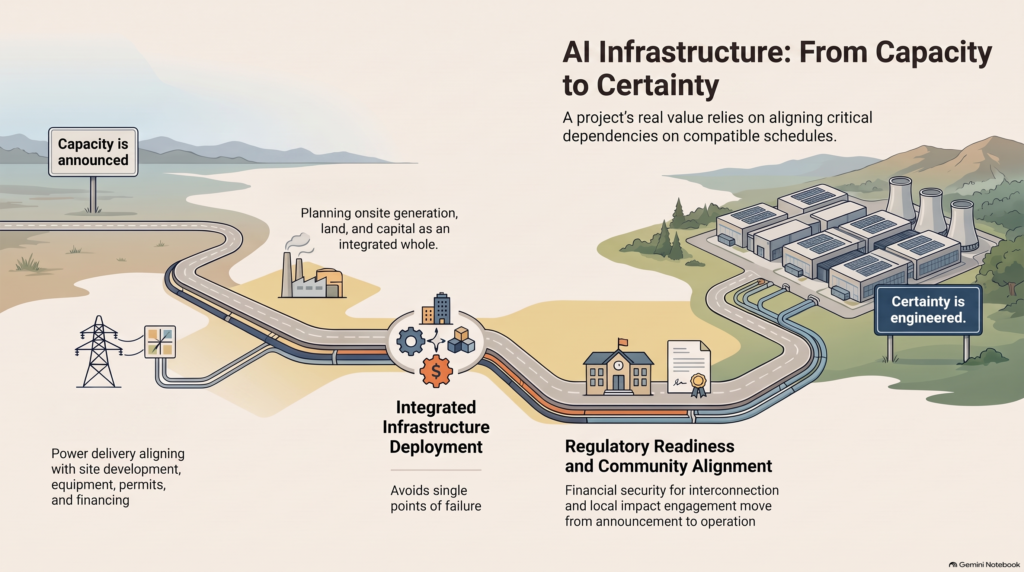
    A project’s real value depends on several linked conditions: a site that can be developed, power that can be delivered, equipment that can be procured, financing that can support the timeline, permits that can be secured, and a community willing to live with the project. If one critical dependency remains uncertain, the announced capacity may be far from usable compute.

    The signals are converging

    Recent developments point toward a more coordinated approach to AI infrastructure.

    In the United States, utility and regulatory processes are placing greater emphasis on whether large-load projects are financially ready and accountable for the infrastructure costs they create. Texas has adopted financial security requirements for large-load interconnection requests, while federal regulators have also focused on cost recovery and protections for existing customers.

    In Japan, a project involving JERA, Dell, and RHAELM brings together power capabilities, a site, data-center development, financing, and AI infrastructure. The project illustrates the appeal of planning these components as an integrated deployment rather than treating them as separate problems to solve one by one.

    Developers are also pursuing onsite generation. Recent reporting describes growing interest in smaller gas turbines and other behind-the-meter options, partly in response to equipment lead times and the challenge of securing grid connections. Onsite power may offer a different schedule path, but it does not erase the trade-offs: fuel supply, permitting, emissions, cost, and the eventual relationship with the grid still matter.

    Community relationships are becoming a more visible part of the infrastructure strategy as well. AWS recently announced a multiyear investment in programs for communities near its U.S. data centers. These commitments do not guarantee public support, but they show that local impact and engagement are now part of the deployment conversation.

    From announced capacity to predictable dependencies

    These examples are different, but they point in the same direction: the challenge is no longer just assembling enough capacity. It is coordinating the conditions that allow capacity to become operational.

    That means executives may need to ask a broader set of questions:

    • Is the power timeline credible, and what assumptions does it depend on?
    • Who pays for the upgrades needed to serve the load?
    • Are land, permits, equipment, and financing progressing on compatible schedules?
    • If grid power is delayed, what alternatives are available—and what new risks do they create?
    • How are local costs, benefits, and concerns being addressed?

    These questions do not replace the traditional focus on capacity. They make the capacity claim more useful by connecting it to execution.

    Certainty as a competitive advantage

    “Certainty” here does not mean that every project outcome is guaranteed. Large infrastructure projects will always involve uncertainty.

    It means that fewer critical dependencies are left unresolved, that assumptions are visible, and that decision-makers have a credible plan for what happens when conditions change.

    As AI infrastructure scales, the strongest projects may not be the ones with the largest headline number. They may be the ones that can show how power, capital, land, equipment, compute, and community considerations fit together—and how the project can move from announcement to operation.

    The optimization target is shifting from “How many gigawatts can we announce?” to “How many dependencies can we make predictable?”

    In AI infrastructure, certainty is becoming part of the product.

  • The New AI Infrastructure Product May Be the Repeatable Campus

    The conversation about AI infrastructure often centers on visible constraints: access to electricity, data center capacity, land, and advanced computing equipment.

    A new partnership in Japan points to a less visible constraint: the complexity of coordinating those pieces into a functioning project.

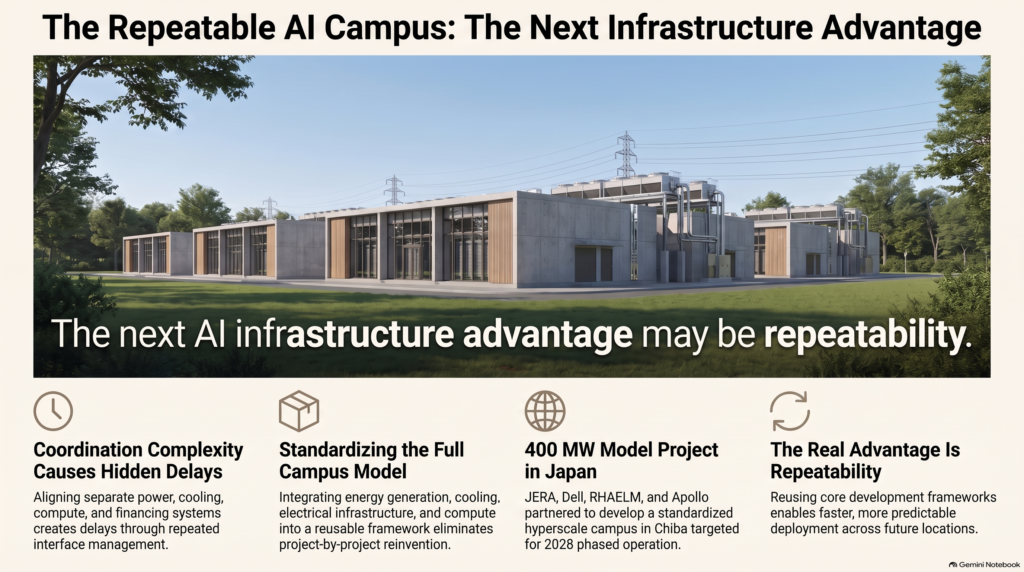
    JERA, Dell Technologies, and RHAELM have signed a memorandum of understanding to develop a standardized model for AI infrastructure in Japan. The model is planned to start with a 400 MW class hyperscale data center project in Chiba. JERA is expected to provide the site and power capacity; RHAELM leads project delivery; and Dell contributes standardized, rack scale AI infrastructure. Apollo is expected to serve as RHAELM’s strategic investment and financing partner. 

    The announcement is notable not simply because of the project’s size. It is also an attempt to treat infrastructure development as a model that could be repeated.

    Project complexity is a constraint of its own

    A large AI campus brings together systems that are often planned and delivered by different organizations. The project has to align its site, energy supply, electrical infrastructure, cooling, computing equipment, financing, construction, and operating model.

    Each interface creates work: decisions to coordinate, dependencies to manage, and potential delays to resolve. If every project requires partners to define those interfaces from the beginning, the development process can remain slow even when the necessary equipment and capital are available.

    Standardization aims to reduce some of that repeated design and coordination work. JERA describes the initiative as a standardized, repeatable model intended to integrate power generation, electrical infrastructure, cooling, and AI computing. Dell’s rack scale infrastructure is meant to standardize the compute layer, while RHAELM leads project delivery. 

    In practical terms, the goal is not necessarily to make every campus identical. It is to identify which components, decisions, and working relationships can be reused—and which must be adapted to local conditions.

    The campus as a coordinated product

    This suggests a broader way to think about AI infrastructure. The product being delivered may not be only a building, a power contract, or a rack of servers. It may be a coordinated campus model that combines those elements in a form that can be developed again.

    That model could have value if it makes future projects easier to scope, finance, engineer, and deliver. Reusing parts of the development approach could reduce the amount of project-by-project reinvention.

    This is an inference about the potential of the model, not a result the announcement has demonstrated. The MoU sets out a plan. The Chiba project will be an early test of whether the approach works in practice.

    Standardization does not erase local constraints

    A repeatable framework cannot make every location interchangeable. Each site still has its own power and grid conditions, permitting requirements, cooling needs, construction environment, financing terms, and operating considerations.

    Standardized compute infrastructure also does not, by itself, guarantee that power will be deliverable when needed or that every other part of the project will arrive on schedule. It can address a portion of the development challenge while leaving other constraints to be solved.

    That is why the most useful question is not whether standardization eliminates complexity. It is whether the partners can reduce enough of the repeated complexity to make later projects faster and more predictable.

    The real test is repeatability

    Reuters reports that the Chiba facility is expected to begin operating in phases in 2028 and reach full capacity in 2029. The companies have also described broader ambitions to develop additional AI data center capacity in Japan. Those are plans and targets; the delivery record is still ahead. 

    The evidence to watch will be concrete: whether the project advances on schedule, whether the partners reuse the model at other sites, and whether later deployments show less development friction.

    AI infrastructure still needs more power, equipment, capital, and sites. But the industry may also need a more repeatable way to combine them.

    The next AI infrastructure advantage may come from turning a complex campus project into a model that can be delivered again.

    Source note: The partnership details above are based on JERA’s October 1 announcement and Reuters’ reporting. The assessment of standardization’s potential benefits is analysis; the proposed model has not yet demonstrated repeat deployments.