Category: Future of Tech

  • AI Coding Costs Are a Workflow Problem, Too

    When businesses look for ways to reduce AI costs, the first move is often to compare model prices or switch to a smaller model.

    That can help. But a recent study points to another place to look: the workflow surrounding the model.

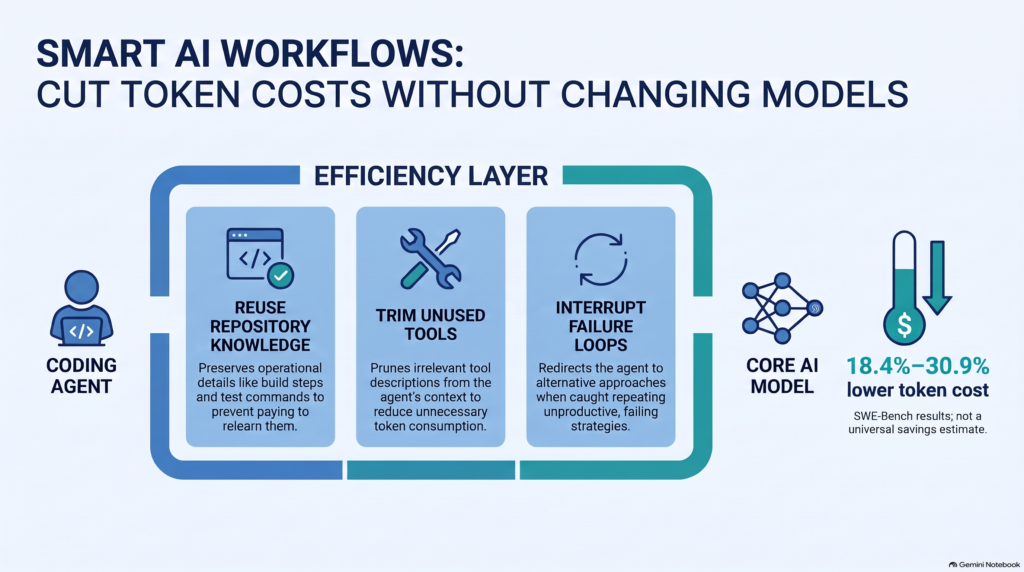
    Researchers introduced TokenEconomizer, an external controller that aims to reduce avoidable token use in AI coding agents. It does not change the underlying model. Instead, it learns from prior work in a repository and adjusts how later tasks are handled.

    In the study, the researchers tested five agent–model configurations on 277 SWE-Bench tasks across six repositories. They reported 18.4%–30.9% lower mean cache-aware token cost, including the controller’s own overhead. Task success improved in four of the five configurations; in the fifth, it fell by one percentage point.

    Those are promising results, not a forecast for every company’s AI bill. The evaluation used benchmark tasks, and the authors note that the SWE-Bench task sequences were related but independent fixes rather than actual developer sessions. Still, the study offers a useful business lesson: workflow design can affect AI economics.

    Where coding-agent costs can accumulate

    An AI coding agent may spend tokens on far more than the code change itself. It can repeatedly read context, load tool definitions, rediscover how a repository works, and retry approaches that keep failing.

    Each cost may look small in isolation. Across many tasks and repeated sessions, they can add up.

    TokenEconomizer targets three sources of that repeated effort:

    • Rediscovering operational details. If an agent repeatedly learns that a particular test command works, or that a build step must come first, the controller can preserve that lesson for future tasks.
    • Loading tools that rarely get used. Tool descriptions can be included in the agent’s context even when those tools are not relevant to a given repository. The controller can prune tools that remain unused.
    • Continuing an unproductive failure loop. When an agent appears stuck repeating the same failed approach, the controller can prompt it to try another direction.

    The pattern is less “make every answer shorter” and more “stop paying repeatedly for avoidable work.”

    What the result means for business leaders

    The study does not show that a workflow controller will reduce every organization’s total AI spend by 18%–31%. It measures cache-aware token cost in specific coding-agent configurations and benchmark tasks. Real-world results will depend on the agent, the tasks, the repository, the tools, and how often work repeats in the same environment.

    But it does challenge a narrow view of AI cost management. Model pricing is one lever. So are task design, context management, tool configuration, and the way teams capture useful operational knowledge.

    For an organization that uses coding agents regularly, the practical question is not just, “Which model costs less per token?” It is also, “How much of our usage is spent solving the task—and how much is spent relearning the workflow?”

    A practical way to test the idea

    Start with one recurring coding workflow and establish a baseline. Track token cost per task, completion or pass rate, retries, tool use, and human correction time. Then pilot workflow changes against a comparable set of tasks.

    Judge the result by cost per successfully completed task, not token savings alone. A lower token bill is not an efficiency gain if it comes with more failures, rework, or developer time.

    The key is to preserve quality while reducing repeated waste. In the TokenEconomizer study, the researchers used an external controller to make that tradeoff more favorable in their tested settings—without changing the underlying model.

    For businesses adopting AI coding tools, that is a useful operational question to take back to the team:

    Where is our AI workflow paying to learn the same lesson twice?

    Source: Aaron J. Li et al., “TokenEconomizer: Experience-Driven Black-Box Cost Control for Coding Agents,” October 15, 2026. https://arxiv.org/abs/2610.22732
  • The Next AI Power Plant May Not Look Like a Traditional Power Plant

    AI infrastructure is changing the conversation about electricity supply. Data centers need large, dependable amounts of power, while new generation and transmission can take years to plan and build. As a result, utilities and technology companies are considering a wider set of generation options.

    American Electric Power’s planned fuel-cell project near Cheyenne, Wyoming, is one example. Announced on October 14, the project is expected to provide 702 megawatts of generation for Google under a 20-year power purchase agreement. AEP estimates the investment at approximately $4 billion. Construction is planned to start in 2026, with the facility expected to be fully operational by the end of 2028. The project company, Cheyenne Fuel Cell LLC, is approximately 92% owned and controlled by AEP, with the remaining ownership held by funds advised by Basalt Infrastructure Partners. 

    Why fuel cells enter the AI power conversation

    Fuel cells generate electricity through an electrochemical process. Unlike a combustion-based generator, they do not burn fuel to produce electricity. Bloom Energy’s solid oxide systems can operate on natural gas, biogas, or hydrogen. This gives developers several possible fuel pathways, though the project’s actual fuel choice and supply arrangements matter to its cost and emissions. 

    The technology can therefore broaden the generation toolkit. A large customer may be able to contract for a dedicated source of on-demand electricity without relying solely on new conventional generation or waiting for grid upgrades to serve every increment of demand. That does not mean fuel cells replace the grid. It means they may become one part of a portfolio that includes grid supply, renewables, storage, conventional generation, and other emerging technologies.

    The scale of this project is also significant. At 702 MW, it is not a small backup installation. It is a large generation development with a substantial capital commitment and a long-term customer relationship. The structure links an energy supplier, a technology provider, an infrastructure investor, and a major electricity customer.

    The contract creates visibility, not certainty

    A 20-year power purchase agreement provides a long-term commercial framework. It signals that Google expects a sustained electricity need in the Cheyenne area and that AEP sees an opportunity to invest in dedicated generation for a large customer. Reuters also reported that Google has a separate arrangement with Black Hills Corp. for generation supporting its proposed data center in the area. 

    However, a long-term agreement does not by itself establish the final price of electricity, the project’s full risk allocation, or its performance over time. The economics will depend on details such as fuel procurement, financing, maintenance, operating costs, construction execution, and the terms that govern availability and performance. Those details are not all provided in the public announcement.

    Emissions claims need to be measured in operation

    AEP says the technology generates electricity without combustion of natural gas and that the project includes plans to integrate carbon-capture technology, with the goal of delivering near-zero-emissions power. Those statements describe the project’s design intent. They are not a published, measured operating emissions result. 

    Fuel-cell generation should not be described as inherently zero-carbon. Bloom notes that systems running on natural gas produce carbon emissions, while fuel choice affects the emissions outcome. The project’s eventual impact will depend on what fuel it uses, how that fuel is sourced, and whether carbon capture is installed and performs as expected. 

    For executives and policymakers, the useful questions are concrete:

    • What fuel will the facility use, and how secure is the supply?
    • What will the delivered power cost over the contract term?
    • What availability and reliability levels are guaranteed?
    • What emissions will be measured at the facility, including any upstream fuel impacts?
    • What carbon-capture system is planned, and how will its performance be verified?
    • What happens if construction, fuel delivery, or equipment performance falls behind plan?

    The broader signal: diversify generation, then verify performance

    The AEP–Google project illustrates a broader shift. AI-related electricity demand is encouraging new commercial arrangements and more varied generation technologies. The potential value of fuel cells is not that they solve every power constraint. It is that they add another possible source of dependable generation that can be evaluated alongside other options.

    The decision standard should remain consistent across technologies: compare delivered cost, dependable output, fuel risk, construction schedule, emissions, and operational performance. A promising configuration becomes useful infrastructure only when it can demonstrate those outcomes.

    The power plant of the AI era may look different from the traditional model. Its business case still has to pass familiar tests.

    How much dependable power will it deliver, at what cost, with what fuel and emissions profile—and can the project prove those results over time?

  • A $1.5 Billion AI Drug Deal Shows the Difference Between Price and Potential Value

    AstraZeneca’s October 15 collaboration with insitro offers a useful look at how a buyer and a specialist partner can divide payment across the life of a high-risk project.

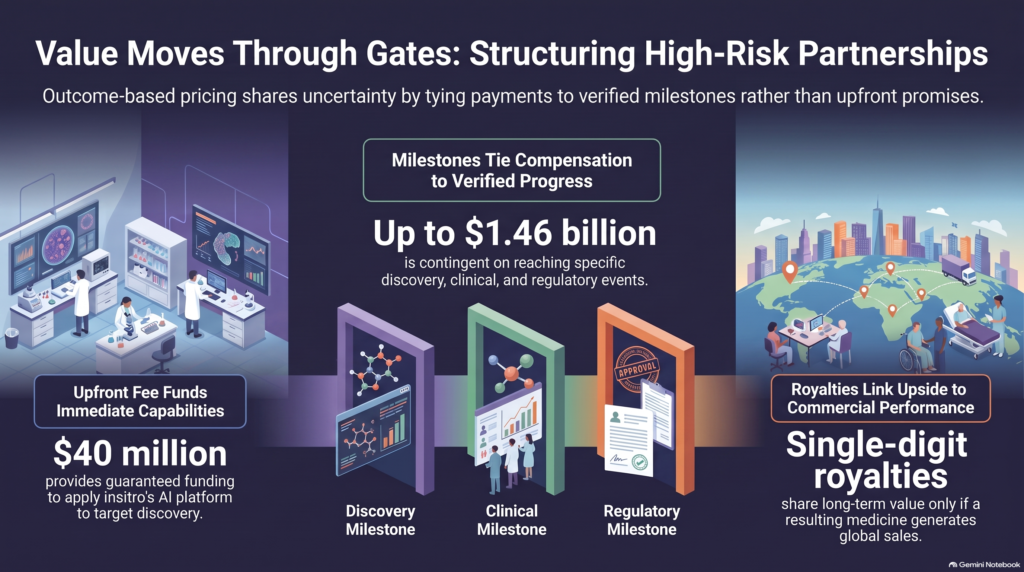
    The announced terms include a $40 million upfront payment, eligibility for up to approximately $1.46 billion in potential discovery, development, and commercial milestone payments, and potential single-digit royalties based on global sales. AstraZeneca will have exclusive worldwide rights to advance selected programs identified through the collaboration. The milestone amount is contingent, and royalties depend on products reaching the market and generating sales. The headline value should not be read as guaranteed revenue for insitro. (astrazeneca.com)

    Three layers of compensation

    The agreement combines three types of payment, each attached to a different point in the work and risk.

    1. Upfront compensation funds the work

    The $40 million upfront payment gives the collaboration immediate economic value. It recognizes the capabilities and work brought into the partnership while providing funding before the long path from discovery to commercial sales is known.

    In this case, insitro applies its Virtual Human platform to identify causal disease biology and advance AstraZeneca-nominated targets from discovery toward development candidates. AstraZeneca leads clinical development, regulatory work, and commercialization. (insitro.com)

    That division matters. The upfront amount is not merely an hourly fee. It sits within an agreement covering specialized capabilities, research activity, and rights to pursue selected programs.

    2. Milestones tie payment to defined progress

    The potential milestone payments connect additional compensation to future discovery, development, and commercial achievements. In principle, a milestone makes payment depend on an agreed event rather than time spent.

    But a milestone is only useful if the parties define it clearly. The contract needs to say what qualifies, who verifies it, what evidence is required, when payment is due, and what happens if the project changes direction. Otherwise, “pay for progress” can turn into a dispute over what progress means.

    Milestones also create a way to share risk. The specialist partner may earn more if programs advance, while the buyer avoids paying the entire potential value before results are known. The partner, in turn, accepts that some of the potential compensation may never be earned.

    3. Royalties connect compensation to commercial performance

    Potential royalties add a longer-term layer: if a resulting medicine is commercialized and produces sales, insitro may receive a share. That is different from a payment for completing a research task. It ties future compensation to commercial performance.

    Royalties also carry more uncertainty. A program must survive scientific, clinical, regulatory, and commercial hurdles before sales exist. The deal therefore places some potential upside far into the future, where outcomes are uncertain and the value of future payments differs from cash received today.

    The value is in the partnership, not just the AI

    It would be easy to describe this as a company licensing AI and another company paying for it. That misses the broader arrangement.

    The announced collaboration combines insitro’s AI-enabled biological discovery work with AstraZeneca’s clinical development, regulatory, and commercialization capabilities. It also grants AstraZeneca exclusive worldwide rights to advance selected programs. The commercial structure reflects an exchange of capabilities, work, rights, and risk—not simply access to a model. (astrazeneca.com)

    That distinction is important for businesses selling AI-enabled expertise. Buyers rarely pay a premium just because AI was used. They pay when the work helps solve a consequential problem, produces evidence they can evaluate, and fits into a process that can turn the work into business value.

    What entrepreneurs can take from the deal

    Most consulting firms should not copy a pharmaceutical deal’s royalties or long development timeline. The transferable idea is to build a pricing structure that matches compensation to the work and the outcome.

    A business could combine:

    • A base fee for discovery, setup, access, or reserved capacity.
    • Milestone payments for defined and accepted outputs, such as a validated workflow, completed implementation, or measurable quality threshold.
    • A success fee or revenue share when the result can be measured and the provider’s contribution is clear.

    This structure should also protect both sides. Define the baseline, measurement method, data source, acceptance criteria, payment trigger, time period, and responsibilities. Address what happens when the client changes scope, delays implementation, or controls an important part of the result. Keep guaranteed compensation sufficient to fund the work, especially when results depend on external factors.

    Outcome-based pricing is not “charge more if the client gets lucky.” It is a deliberate agreement about what value means, what evidence will prove it, and how the parties will share uncertainty.

    The AstraZeneca–insitro deal makes that structure visible: some compensation is paid upfront, more may follow verified milestones, and additional upside may depend on commercial success. The headline amount captures the maximum potential under the agreement. The actual economics depend on what gets achieved.

    Entrepreneur question: Which part of your expertise could be priced around verified progress or results instead of hours alone?

  • Why a Gigawatt of Electricity Doesn’t Mean a Gigawatt of AI Compute

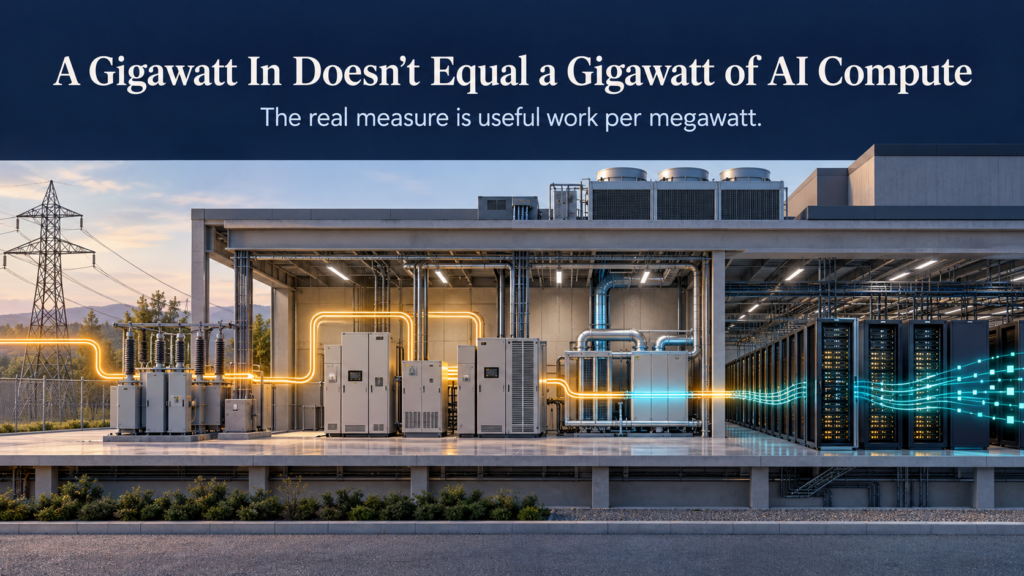
    A data center’s power capacity tells us how much electricity it can draw. It does not tell us how much useful AI work the facility will produce.

    That difference matters as companies compete for power, build larger campuses, and commit billions of dollars to AI infrastructure. A megawatt secured at the grid connection is only the beginning of the measurement.

    Power has to travel through the system

    Electricity entering a data center must be converted and distributed before it reaches computing equipment. The facility also needs cooling, monitoring, backup systems, and other infrastructure to operate reliably.

    Then there is the equipment itself. A GPU can be installed and powered without running at full utilization. A poorly configured rack, a failed component, or a system restart can reduce productive output even while the facility continues to draw power.

    The result is a gap between electricity consumed and useful computation delivered.

    What the reported 60–70% estimate tells us

    On October 14, TechRadar reported remarks from NVIDIA representatives at a Vertiv event suggesting that roughly 60–70% of electricity drawn by some AI data centers supports AI processing. The report described the remaining share as associated with cooling, power distribution and conversion, equipment configuration, failures, and restarts.

    That figure is an industry estimate reported from executive remarks. It is not an independently audited average for all data centers. Facility design, workload, equipment, climate, operating practices, and the way “AI processing” is measured can all affect the result.

    The estimate is still useful as a prompt: capacity figures alone do not reveal how efficiently a facility turns electricity into productive work.

    “Non-compute” power is not automatically waste

    Cooling and backup systems are necessary to keep high-density computing equipment within operating limits and protect service continuity. Power conversion and distribution are also part of delivering electricity safely to the IT load.

    The goal is not to eliminate every watt that does not go directly to a processor. The goal is to understand the full system, reduce avoidable losses, and make sure the infrastructure investment supports dependable output.

    A facility designed for peak demand and contingencies may also have capacity that is not used continuously. That may be appropriate for resilience, but it raises a management question: how much of the available infrastructure is producing useful work under typical operating conditions?

    Measure the output, not just the input

    “Gigawatt of AI compute” is shorthand. A gigawatt measures electrical power; compute output is measured through completed work and system performance.

    For executives, that means asking for more than a facility’s contracted power or nameplate capacity. Useful measures could include:

    • Electricity delivered to the facility and to IT equipment
    • AI workload throughput, such as completed jobs or tokens generated
    • Accelerator utilization and periods of idle or degraded operation
    • Cooling and power-system overhead
    • Availability, restart frequency, and time spent operating below target

    These measures need consistent definitions and a clear time period. A peak result, a design target, and an observed operating average are different kinds of evidence.

    The strategic implication

    When power is scarce, improving the amount of useful computation produced from existing electricity can be as important as securing more supply.

    That makes infrastructure efficiency an operating and capital-allocation issue. Better power delivery, cooling, equipment configuration, workload scheduling, and maintenance may help increase productive output without assuming that every problem can be solved by adding another megawatt.

    The reported 60–70% estimate should be treated as a signal to investigate, not a benchmark to apply blindly. Each operator needs facility-level evidence to understand where power goes and what work it enables.

    The executive question is therefore not only, “How much power can this data center draw?”

    It is: How much useful, reliable AI work does each megawatt deliver—and how do we know?

  • Financial Regulators Are Moving from AI Risk Plans to Resilience Exercises

    A response plan can look complete on paper and still fail under pressure.

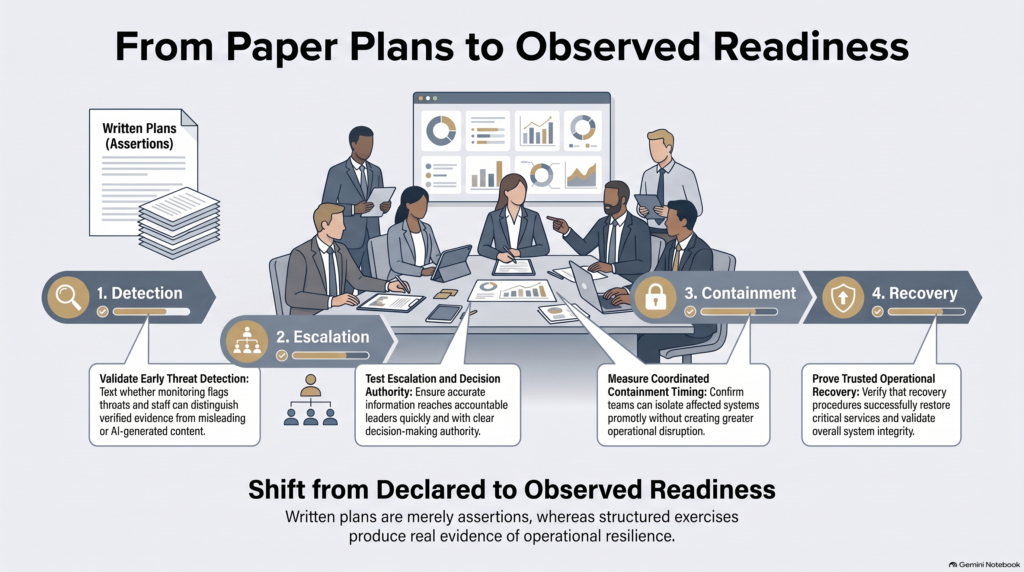
    That is why the G7’s agreement to conduct tabletop exercises simulating AI-enabled cyberattacks on the financial sector matters. Finance ministers and central bank governors have backed exercises designed to test existing response procedures. Depending on the scenarios, private financial institutions may also take part. The results are expected to help assess current protocols and identify improvements. (reuters.com)

    The announcement does not mean the G7 has already tested those procedures. It does show that the conversation is moving toward operational readiness: asking whether people, processes, and systems can work together during a realistic incident.

    A plan is not proof of readiness

    A written incident-response plan can describe who should be notified, who has authority to act, and how systems should be restored. But those instructions are only useful if they work in practice.

    During a fast-moving cyber incident, teams may need to determine whether an alert is credible, understand which services and third parties are affected, escalate to the right decision-makers, contain the threat, communicate accurately, and restore critical operations. Each step depends on clear ownership, timely information, and decisions that can be made under pressure.

    An AI-enabled scenario adds questions that organizations should be prepared to answer. Did monitoring identify the activity? Could staff distinguish verified evidence from misleading or AI-generated content? Were decision-makers given reliable information quickly enough? Could the organization isolate affected systems without creating greater disruption? Did recovery procedures restore trusted operations?

    The exercise is valuable because it can expose gaps between the documented process and the organization’s ability to carry it out.

    What a useful exercise should reveal

    A tabletop exercise should do more than confirm that participants attended and discussed a scenario. It should create evidence about how the response actually unfolded.

    For example, an organization can record:

    • When the incident was detected and when it was escalated.
    • Who made key decisions, what information they had, and whether authority was clear.
    • Whether containment actions were timely and coordinated across teams and providers.
    • How the organization maintained or restored critical services.
    • Which assumptions, dependencies, or communication paths failed.
    • What corrective actions were assigned, to whom, and by when.

    Those records help distinguish a rehearsed response from a demonstrated capability. They also give leadership a practical way to track whether identified weaknesses are fixed and retested.

    The governance question is whether the controls connect

    Detection, escalation, containment, and recovery are often described as separate capabilities. In a real incident, they form a chain. A strong detection tool has limited value if the alert reaches no accountable decision-maker. A clear escalation path cannot help if teams lack authority to contain the incident. Recovery plans are difficult to trust if the organization has not tested whether it can restore systems and validate their integrity.

    That is where exercises can help leaders see whether controls work together across business units, technical teams, senior management, and external partners. They can also test how participants make decisions when facts are incomplete and the incident is still developing.

    The G7 agreement is a meaningful step toward operational testing. The next measure of progress will be what the exercises uncover, what changes follow, and whether those changes are tested again.

    For financial institutions, the broader lesson is straightforward: a procedure is an assertion about readiness. A well-designed exercise produces evidence about readiness.

    Entrepreneur question: How can your organization show that its AI risk-management procedures work when the situation is uncertain, time-sensitive, and shared across teams?

  • The Next AI Infrastructure Bottleneck May Be Chips Waiting on Other Chips

    AI infrastructure discussions often begin with the most visible asset: the accelerator. How many GPUs or other AI processors can a company buy, and when can they be installed?

    But installed capacity is only part of the equation. Those processors must also exchange data, coordinate work, and receive instructions from the software stack. If those connections cannot keep pace with the workload, adding more processors may not deliver a proportional increase in useful compute.

    That makes networking and integration a growing part of the economics of AI infrastructure.

    Compute depends on more than the processor

    An AI cluster is a system of connected components. Processors move data between memory, storage, and other processors while workloads are divided, coordinated, and recombined. The network affects how quickly those exchanges happen and how well the system handles congestion or failures.

    Two networking jobs matter here. Scale-up networking connects accelerators within a pod or rack. Scale-out networking connects systems across racks and throughout a data center. A workload can depend on both.

    When data movement or coordination becomes a constraint, some processors may wait for information or for other parts of the workload to finish. The hardware is present, but its potential output is not being fully realized. That can weaken the return on expensive infrastructure investments and complicate capacity planning.

    What Token Fabric is trying to do

    On October 8, Nvidia-backed Upscale AI introduced Token Fabric, a networking architecture intended to support AI processors from different suppliers. The company describes it as a combination of scale-up and scale-out networking, systems, and shared software for managing operations. Reuters reported that the platform is expected to roll out in stages, with the first component planned for the fourth quarter and the broader platform through 2027. Upscale says general availability is planned for early 2027. (reuters.com, upscale.com)

    The proposal addresses a practical challenge for operators: networking has often been assembled from separate components that customers must integrate and manage. A more unified approach could simplify parts of that work and make it easier to build clusters containing different types of accelerators.

    That is the opportunity. It is not yet proof that the architecture will deliver a specific utilization gain or make mixed-vendor systems simple to operate. Those results will depend on deployment conditions and independent performance evidence.

    Interoperability is useful, but it is not automatic

    The possibility of using multiple accelerator suppliers is attractive for organizations that want more choice in hardware procurement or want to match different processors to different workloads. It could also reduce reliance on a single hardware ecosystem.

    However, networking compatibility is only one part of interoperability. A system still needs suitable software frameworks, drivers, compilers, memory behavior, and workload orchestration. Operators must also understand how performance changes when different processors share a system.

    In other words, “connects different processors” does not necessarily mean every processor can be substituted freely, or that every workload will run equally well across all of them. The relevant test is whether the full system performs reliably and economically for the workloads a customer actually runs.

    The business metric is useful output

    For decision-makers, the central question is not simply how many processors are installed. It is how much useful work the organization gets from the complete system, at what cost, and with what operational burden.

    That means evaluating utilization alongside measures such as workload throughput, latency, energy use, network performance, software compatibility, and the cost of operating the environment. A network upgrade that improves one technical metric may not improve the business outcome if it adds complexity or fails to support the applications that matter.

    The same discipline applies to claims about future capacity. Product roadmaps and announced availability dates are signals about where vendors are investing. They are not substitutes for customer deployments, workload-level results, and independently reviewable performance data.

    The next bottleneck is system-level

    AI infrastructure is moving beyond a simple race to install more chips. The economics increasingly depend on how compute, networking, software, power, and operations work together.

    Token Fabric is one example of vendors trying to address that system-level problem and support more heterogeneous infrastructure. The broader industry question is whether these architectures can make processors easier to connect and keep productively occupied—without creating new integration and management burdens.

    The next generation of AI capacity may be shaped not only by how many chips organizations can obtain, but by how effectively those chips can work together.

  • The Next AI Megawatt May Come From a Power Plant We Already Built

    As demand for electricity grows, the conversation often turns to new generation: new plants, new transmission, and new infrastructure. Those investments matter. But a recent Google–Constellation agreement points to another part of the supply equation: increasing output from assets that are already operating.

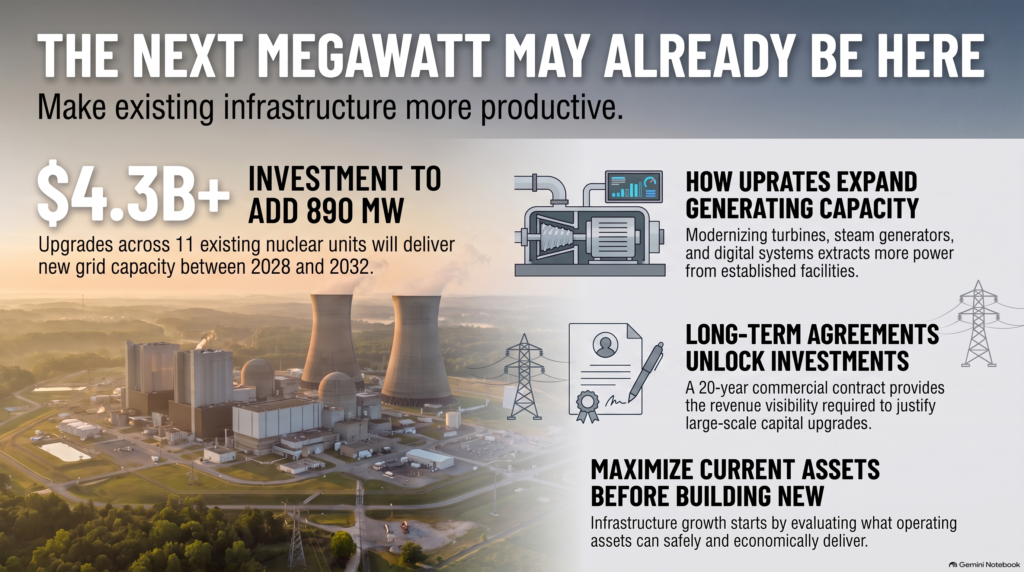
    Announced October 6, the companies’ 20-year power purchase agreement supports upgrades at 11 existing Constellation nuclear units across six sites in Illinois, Pennsylvania, and New Jersey. The upgrades are expected to add 890 megawatts of nuclear capacity to the PJM grid. Constellation says it plans to invest more than $4.3 billion in the work. The first uprate is expected in 2028, with the full 890 MW planned by the end of 2032. 

    This is not a new nuclear plant coming online today. It is a long-term investment plan to increase output from existing reactors.

    What an uprate changes

    A nuclear uprate increases a plant’s generating capacity by upgrading equipment and systems. The companies cite work involving turbines, steam generators, and digital control systems. The goal is to produce more electricity from an existing facility while maintaining the requirements that govern its safe and reliable operation. 

    That distinction matters. An operating plant already has a site, grid connections, and much of the supporting infrastructure. Upgrading it may offer a different development path from building a new facility. But it still requires substantial capital, specialized engineering, regulatory work, construction planning, and time.

    Why the commercial structure matters

    The 20-year agreement provides a long-term customer commitment associated with the planned upgrades. That kind of revenue visibility can help a generator justify capital investment in equipment and capacity improvements.

    The agreement also sits within a larger power arrangement. Google and Constellation signed a separate 15-year supply contract for another 2,700 MW from Constellation’s PJM generation fleet. That supply is not linked to a specific generating source, so it should not be counted as part of the 890 MW of new nuclear capacity. 

    The distinction between the two agreements is useful: one supports planned incremental nuclear capacity; the other provides long-term revenue certainty for existing generation assets.

    The capital-efficiency lesson

    Capital efficiency does not mean avoiding investment. In this case, the announced program includes more than $4.3 billion in planned investment. The efficiency question is whether targeted upgrades to existing assets can add useful capacity while making productive use of infrastructure already in place.

    That is a different question from simply asking how quickly a new plant can be built. It asks whether the current system contains assets with additional potential—and what investment, operational changes, and approvals are needed to realize it.

    The answer will vary by asset and location. An upgrade is not automatically faster, cheaper, or feasible everywhere. The 890 MW is a target for future delivery, with the first uprate expected in 2028 and the full capacity planned by the end of 2032. 

    A broader infrastructure principle

    For executives assessing electricity needs, the agreement offers a useful lens: examine both new supply and the productivity of existing assets. In power, that can mean evaluating uprates, reliability, grid connections, operating performance, and demand flexibility alongside new construction.

    The broader lesson applies across infrastructure. Growth does not always begin with acquiring or building another asset. Sometimes it begins by asking what the current asset base can safely and economically deliver—and what commitment will make the required investment possible.

    The next megawatt may come from a new plant. It may also come from making an existing one work harder.

    Source note: Constellation’s announcement says 890 MW will be added to the PJM grid through the planned nuclear upgrades; Google’s post provides the end-of-2032 target. The separate 2,700 MW agreement is not source-specific. 

  • AI Can Help Design the Chip. Verification Still Has the Final Word.

    AI is moving deeper into technical work. The latest example is a September 30 announcement from Synopsys and OpenAI: the companies plan to develop GPT-Synopsys, a specialized model for semiconductor design.

    The model is intended to combine OpenAI’s AI capabilities with Synopsys’ electronic design automation tools and chip-design expertise. Synopsys says it is being developed to reason about chip design and verification and to operate its tools. 

    That development points to a practical question for companies adopting AI in engineering and other high-consequence work:

    How do you use AI to increase the pace of work while preserving confidence in the result?

    A design proposal is not a verified design

    Chip design is not complete when a system produces a candidate solution. A design must satisfy engineering requirements and physical constraints before it can be accepted for manufacturing.

    Reuters reported that Synopsys expects traditional computing tools to check the model’s work and determine whether a chip will function. Synopsys’ CEO emphasized the need for high-fidelity validation and sign-off. 

    That is the key governance signal. AI can help generate or refine a solution, but the model’s output does not establish that the solution is correct.

    The same distinction applies in other settings. A system may draft a code change, recommend a credit decision, identify a potential defect, or suggest an engineering configuration. Those outputs may be useful. They still need to be tested against requirements that are explicit, relevant, and independently assessable.

    Keep the roles clear

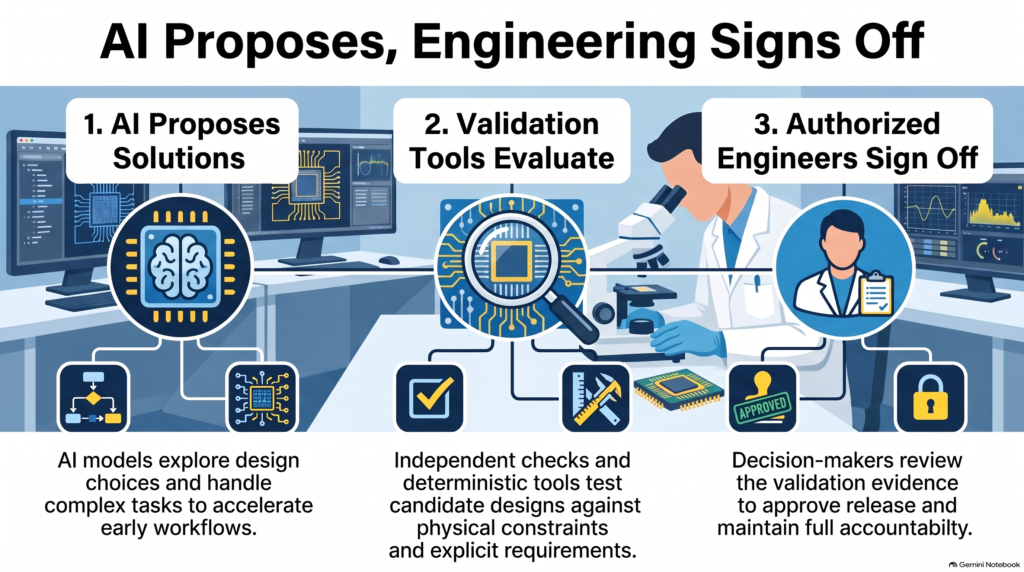
    A sound workflow gives each stage a distinct responsibility:

    1. AI proposes or assists. It can help explore design choices, handle complex tasks, and accelerate parts of the workflow.
    2. Validation tools evaluate. Defined checks test the output against relevant requirements and constraints. Depending on the task, that may involve simulation, deterministic checks, formal methods, or established sign-off processes.
    3. An authorized decision-maker accepts or escalates. The person or team with release authority reviews the evidence and decides what happens next.

    “Formal verification” should be used precisely: it refers to specific methods for proving properties of a system. It is not a generic label for every validation step. In this case, the broader and better-supported point is that established verification and sign-off remain part of the engineering process.

    What governance should make visible

    For a workflow like this to be governable, an organization should be able to answer:

    • What output did the AI produce, and which model or tool version produced it?
    • Which requirements and constraints were used to evaluate it?
    • What checks were run, and what were their results?
    • What happens when a check fails, produces an inconclusive result, or conflicts with another check?
    • Who has authority to accept the result or approve its release?
    • Can the organization connect the accepted result to the evidence reviewed at the time?

    These questions turn “human oversight” from a slogan into an operational control. A person’s name on an approval is not enough if the evidence, artifact, or criteria behind that approval cannot be identified later.

    Faster work still needs defensible decisions

    The point is not to slow down AI-assisted engineering. It is to keep speed from outrunning the organization’s ability to establish whether a result is fit for use.

    The emerging pattern is straightforward:

    AI proposes. Deterministic or otherwise established validation checks. Authorized decision-makers accept.

    That pattern can help organizations capture AI’s contribution while preserving accountability for outcomes. The AI may expand the range of solutions engineers can explore. Validation provides evidence about whether a candidate meets requirements. Decision authority determines whether that evidence is sufficient for release.

    The model can participate in the work. The organization still needs a process that can explain why the work was accepted.

    Capability creates options. Verification creates evidence. Authority turns evidence into an accountable decision.

    Sources

  • AI Infrastructure Is Moving From Maximum Capacity to Maximum Certainty

    The AI infrastructure conversation has been dominated by scale: more data centers, more generation, more chips, more gigawatts.

    Scale is still essential. AI workloads need enormous amounts of compute and power. But a large capacity announcement does not, by itself, mean a project can be financed, built, connected, and operated on a dependable schedule.

    That gap is moving to the center of the conversation.

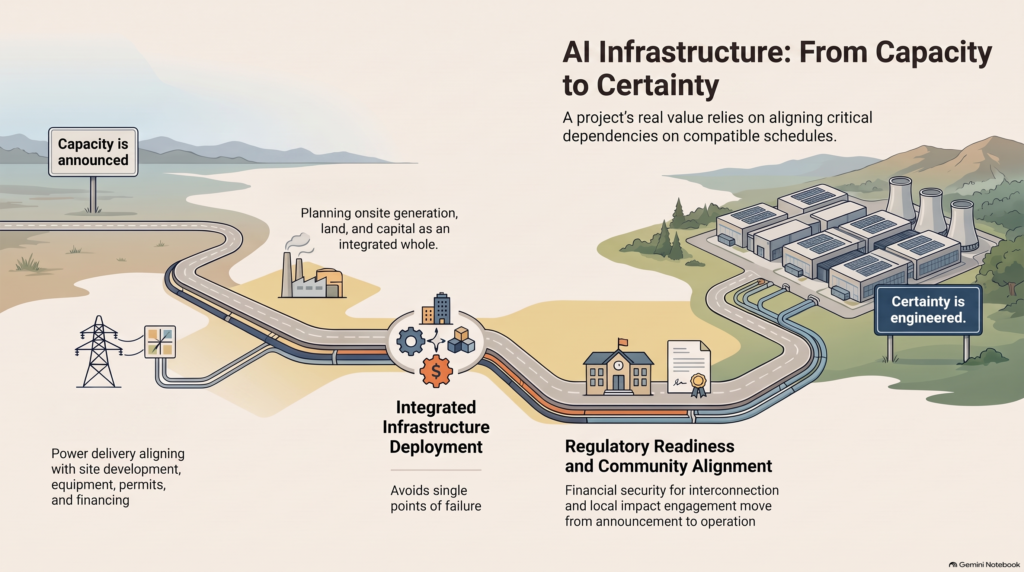
    A project’s real value depends on several linked conditions: a site that can be developed, power that can be delivered, equipment that can be procured, financing that can support the timeline, permits that can be secured, and a community willing to live with the project. If one critical dependency remains uncertain, the announced capacity may be far from usable compute.

    The signals are converging

    Recent developments point toward a more coordinated approach to AI infrastructure.

    In the United States, utility and regulatory processes are placing greater emphasis on whether large-load projects are financially ready and accountable for the infrastructure costs they create. Texas has adopted financial security requirements for large-load interconnection requests, while federal regulators have also focused on cost recovery and protections for existing customers.

    In Japan, a project involving JERA, Dell, and RHAELM brings together power capabilities, a site, data-center development, financing, and AI infrastructure. The project illustrates the appeal of planning these components as an integrated deployment rather than treating them as separate problems to solve one by one.

    Developers are also pursuing onsite generation. Recent reporting describes growing interest in smaller gas turbines and other behind-the-meter options, partly in response to equipment lead times and the challenge of securing grid connections. Onsite power may offer a different schedule path, but it does not erase the trade-offs: fuel supply, permitting, emissions, cost, and the eventual relationship with the grid still matter.

    Community relationships are becoming a more visible part of the infrastructure strategy as well. AWS recently announced a multiyear investment in programs for communities near its U.S. data centers. These commitments do not guarantee public support, but they show that local impact and engagement are now part of the deployment conversation.

    From announced capacity to predictable dependencies

    These examples are different, but they point in the same direction: the challenge is no longer just assembling enough capacity. It is coordinating the conditions that allow capacity to become operational.

    That means executives may need to ask a broader set of questions:

    • Is the power timeline credible, and what assumptions does it depend on?
    • Who pays for the upgrades needed to serve the load?
    • Are land, permits, equipment, and financing progressing on compatible schedules?
    • If grid power is delayed, what alternatives are available—and what new risks do they create?
    • How are local costs, benefits, and concerns being addressed?

    These questions do not replace the traditional focus on capacity. They make the capacity claim more useful by connecting it to execution.

    Certainty as a competitive advantage

    “Certainty” here does not mean that every project outcome is guaranteed. Large infrastructure projects will always involve uncertainty.

    It means that fewer critical dependencies are left unresolved, that assumptions are visible, and that decision-makers have a credible plan for what happens when conditions change.

    As AI infrastructure scales, the strongest projects may not be the ones with the largest headline number. They may be the ones that can show how power, capital, land, equipment, compute, and community considerations fit together—and how the project can move from announcement to operation.

    The optimization target is shifting from “How many gigawatts can we announce?” to “How many dependencies can we make predictable?”

    In AI infrastructure, certainty is becoming part of the product.

  • The New AI Infrastructure Product May Be the Repeatable Campus

    The conversation about AI infrastructure often centers on visible constraints: access to electricity, data center capacity, land, and advanced computing equipment.

    A new partnership in Japan points to a less visible constraint: the complexity of coordinating those pieces into a functioning project.

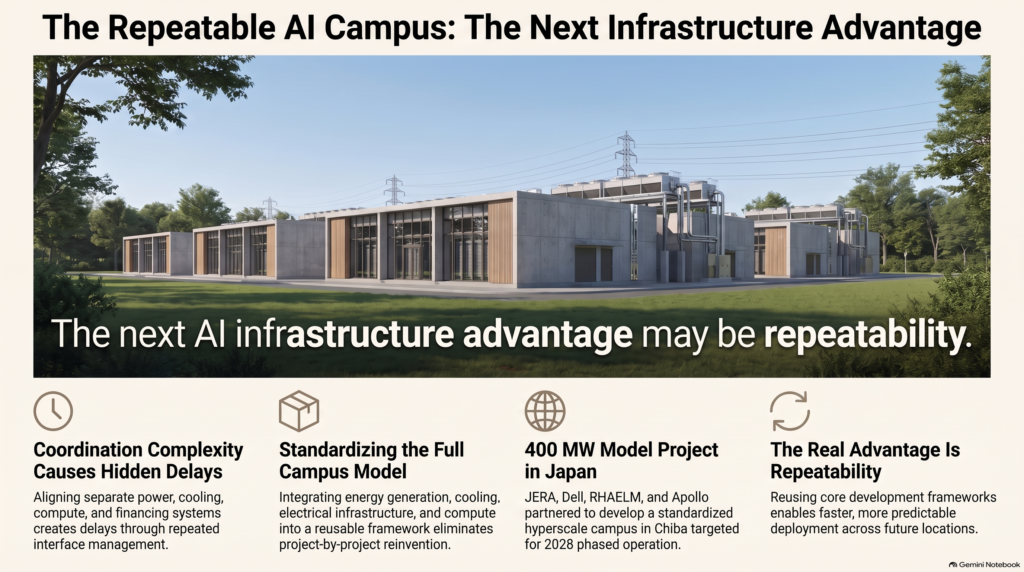
    JERA, Dell Technologies, and RHAELM have signed a memorandum of understanding to develop a standardized model for AI infrastructure in Japan. The model is planned to start with a 400 MW class hyperscale data center project in Chiba. JERA is expected to provide the site and power capacity; RHAELM leads project delivery; and Dell contributes standardized, rack scale AI infrastructure. Apollo is expected to serve as RHAELM’s strategic investment and financing partner. 

    The announcement is notable not simply because of the project’s size. It is also an attempt to treat infrastructure development as a model that could be repeated.

    Project complexity is a constraint of its own

    A large AI campus brings together systems that are often planned and delivered by different organizations. The project has to align its site, energy supply, electrical infrastructure, cooling, computing equipment, financing, construction, and operating model.

    Each interface creates work: decisions to coordinate, dependencies to manage, and potential delays to resolve. If every project requires partners to define those interfaces from the beginning, the development process can remain slow even when the necessary equipment and capital are available.

    Standardization aims to reduce some of that repeated design and coordination work. JERA describes the initiative as a standardized, repeatable model intended to integrate power generation, electrical infrastructure, cooling, and AI computing. Dell’s rack scale infrastructure is meant to standardize the compute layer, while RHAELM leads project delivery. 

    In practical terms, the goal is not necessarily to make every campus identical. It is to identify which components, decisions, and working relationships can be reused—and which must be adapted to local conditions.

    The campus as a coordinated product

    This suggests a broader way to think about AI infrastructure. The product being delivered may not be only a building, a power contract, or a rack of servers. It may be a coordinated campus model that combines those elements in a form that can be developed again.

    That model could have value if it makes future projects easier to scope, finance, engineer, and deliver. Reusing parts of the development approach could reduce the amount of project-by-project reinvention.

    This is an inference about the potential of the model, not a result the announcement has demonstrated. The MoU sets out a plan. The Chiba project will be an early test of whether the approach works in practice.

    Standardization does not erase local constraints

    A repeatable framework cannot make every location interchangeable. Each site still has its own power and grid conditions, permitting requirements, cooling needs, construction environment, financing terms, and operating considerations.

    Standardized compute infrastructure also does not, by itself, guarantee that power will be deliverable when needed or that every other part of the project will arrive on schedule. It can address a portion of the development challenge while leaving other constraints to be solved.

    That is why the most useful question is not whether standardization eliminates complexity. It is whether the partners can reduce enough of the repeated complexity to make later projects faster and more predictable.

    The real test is repeatability

    Reuters reports that the Chiba facility is expected to begin operating in phases in 2028 and reach full capacity in 2029. The companies have also described broader ambitions to develop additional AI data center capacity in Japan. Those are plans and targets; the delivery record is still ahead. 

    The evidence to watch will be concrete: whether the project advances on schedule, whether the partners reuse the model at other sites, and whether later deployments show less development friction.

    AI infrastructure still needs more power, equipment, capital, and sites. But the industry may also need a more repeatable way to combine them.

    The next AI infrastructure advantage may come from turning a complex campus project into a model that can be delivered again.

    Source note: The partnership details above are based on JERA’s October 1 announcement and Reuters’ reporting. The assessment of standardization’s potential benefits is analysis; the proposed model has not yet demonstrated repeat deployments.