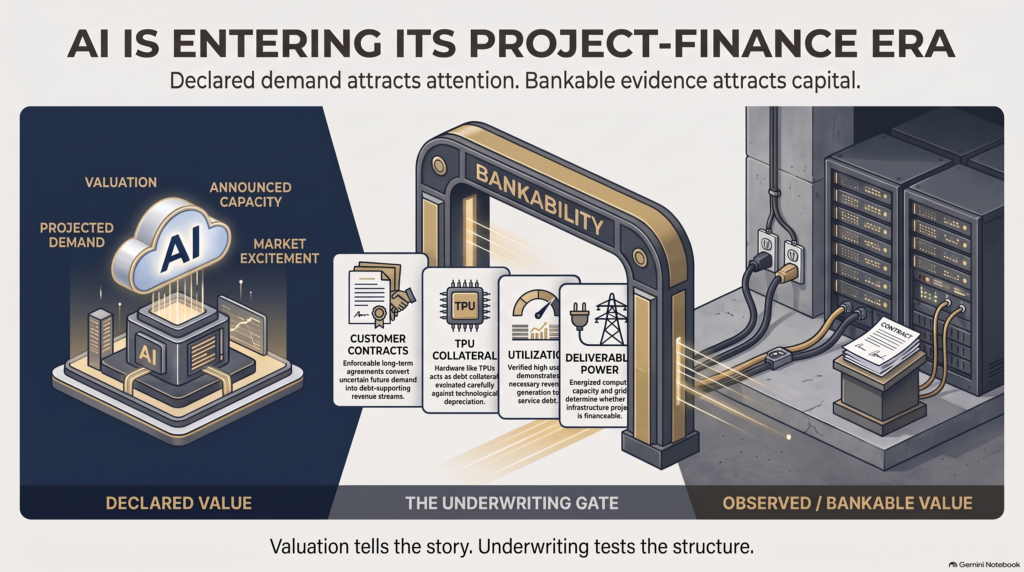
AI Infrastructure Is Entering Its Project-Finance Era
For much of the AI boom, attention has centered on company valuations, model capabilities and venture-capital investments.
That view is becoming incomplete.
The next phase of AI expansion requires physical infrastructure at enormous scale: processors, data centers, substations, transmission capacity, cooling systems and long-term access to electricity. Building that infrastructure requires more capital than even the largest technology companies may want to carry directly on their balance sheets.
That is why one of the most important AI developments of the week came from the financing side of the market.
On September 16, Reuters reported that a consortium of ten banks—including Goldman Sachs, Barclays, BNP Paribas, Sumitomo Mitsui Banking Corporation and Bank of Nova Scotia—was providing approximately $22 billion in financing for Crux AI, a cloud-computing venture backed by Blackstone and Alphabet.
Blackstone had already committed an initial $5 billion in equity. Google is contributing its Tensor Processing Units, along with software and services. The debt is expected to be secured by the TPUs and customer contracts, while the venture is targeting its first 500 megawatts of computing capacity in 2027. The banks may eventually refinance portions of the loan through the bond market. (reuters.com, reuters.com)
Those details deserve more attention than the headline dollar amount.
The capital stack is becoming part of the AI story
This transaction suggests that AI infrastructure is beginning to acquire characteristics commonly associated with project finance.
In traditional project finance, lenders do not rely solely on the reputation or market valuation of a corporate sponsor. They examine the project’s assets, contracts, construction milestones and expected cash flows.
The fundamental question is straightforward:
Can this specific group of assets produce enough reliable revenue to repay the financing used to build it?
That question is now being applied to AI compute.
The collateral is no longer merely an ownership stake in a promising technology company. It can include physical processors and contractual claims on future customer payments.
That represents a significant evolution in how capital is moving through the AI sector.
Money is moving beyond funding companies that develop AI. It is increasingly financing the industrial system required to operate AI at scale.
Contracts are becoming infrastructure
A processor has technical value, but a processor connected to power and committed to a creditworthy customer has financial value.
That distinction explains why customer contracts matter so much to these financing structures.
A long-term contract can transform uncertain future demand into a more predictable stream of revenue. That stream may then support debt financing, which allows the infrastructure provider to purchase more equipment and build additional capacity.
The contract effectively becomes part of the infrastructure.
But not all contracted demand is equally bankable. Lenders will examine the duration of the agreement, the customer’s ability to pay, cancellation provisions, minimum-use commitments and the consequences of delayed delivery.
A large announced customer pipeline may attract attention.
A durable contract with enforceable payment obligations can attract capital.
Utilization is no longer merely an operating metric
When infrastructure is financed with debt, utilization becomes directly connected to debt service.
A data center can be completed. The processors can be installed. Power can be available. But if customers do not use the contracted capacity—or if the contracts allow them to walk away—the economic model can still fail.
This creates an important separation between four different claims:
- Announced computing capacity
- Constructed computing capacity
- Energized computing capacity
- Revenue-producing computing capacity
Those categories are not interchangeable.
The AI sector has spent considerable time discussing how much capacity companies intend to build. Financing markets will increasingly ask how much of that capacity can be delivered, utilized and converted into dependable cash flow.
This is another version of the declared-versus-observed problem.
Declared demand may justify an announcement.
Observed utilization must eventually justify the financing.
AI chips are unusual collateral
The inclusion of TPUs as collateral is particularly revealing.
Processors are physical assets, but they do not behave like conventional infrastructure assets. A transmission line, pipeline or toll road may remain economically productive for decades. Advanced AI processors can face much faster technological and economic depreciation.
A chip may continue functioning while becoming less competitive against a newer generation with better performance, lower energy consumption or a more attractive cost per unit of compute.
That creates several underwriting questions:
- How quickly will the equipment lose economic value?
- Can the processors support multiple customers and workloads?
- How dependent is the platform on one chip architecture?
- What happens to the loan if utilization declines before the debt matures?
- How much value could lenders recover from the hardware in a downside scenario?
The equipment may be tangible, but its future value remains tied to technological relevance.
Power readiness becomes a financial condition
The planned 500 megawatts also connect this transaction to the broader infrastructure constraints surrounding AI.
A processor cannot generate revenue while waiting for electricity.
That means lenders financing AI infrastructure must look beyond chips and customer contracts. They also need confidence in land control, interconnection agreements, permits, construction schedules, cooling capacity and the delivery of dependable power.
An announced 500-megawatt project is not automatically a financeable 500-megawatt project.
The difference lies in whether the capacity can be built, energized and made available when customers expect it.
Grid readiness is therefore becoming more than an engineering concern. It is becoming a credit concern.
Follow what the financing requires
Entrepreneurs and executives trying to understand AI economics should pay attention to more than valuations and funding announcements.
The more useful questions may now be:
- What assets secure the financing?
- Which contracts support the projected revenue?
- How concentrated is the customer base?
- What utilization level is required to service the debt?
- Who carries the risk of construction delays?
- Who absorbs the loss if the equipment depreciates faster than expected?
- Is the power capacity announced, contracted or actually deliverable?
- Will the debt remain with the banks or be distributed through the bond market?
These questions reveal what sophisticated capital providers believe can withstand scrutiny—and where they still require protection.
That does not mean every heavily financed AI project will succeed. It means the AI boom is entering a stage where enthusiasm must increasingly be translated into assets, contracts, milestones and cash flows.
Valuations show what the market hopes an AI company might become.
Financing structures show what lenders are willing to treat as bankable.
As AI infrastructure grows more capital-intensive, that may become one of the clearest ways to distinguish the sector’s declared promise from its observed economic foundation.
